Clawer Ultimate Guide Automated Data: Mastering Web Intelligence
Automated data extraction isn’t just a technical necessity—it’s the backbone of modern decision-making. From competitive intelligence to dynamic pricing, organizations rely on clawer ultimate guide automated data solutions to process vast datasets without manual intervention. Yet, despite its ubiquity, many still grapple with implementation challenges: Which tools balance speed and compliance? How do you ensure scalability without sacrificing accuracy? The answers lie in understanding the ecosystem beyond generic buzzwords.
The right automated data framework doesn’t just scrape—it interprets. It adapts to CAPTCHAs, navigates JavaScript-rendered pages, and respects robots.txt while extracting actionable insights. The gap between raw extraction and strategic intelligence is where clawer ultimate guide automated data becomes indispensable. This guide cuts through the noise, dissecting the mechanics, ethical pitfalls, and future-proofing strategies for professionals who demand precision.
###
The Complete Overview of Clawer Ultimate Guide Automated Data
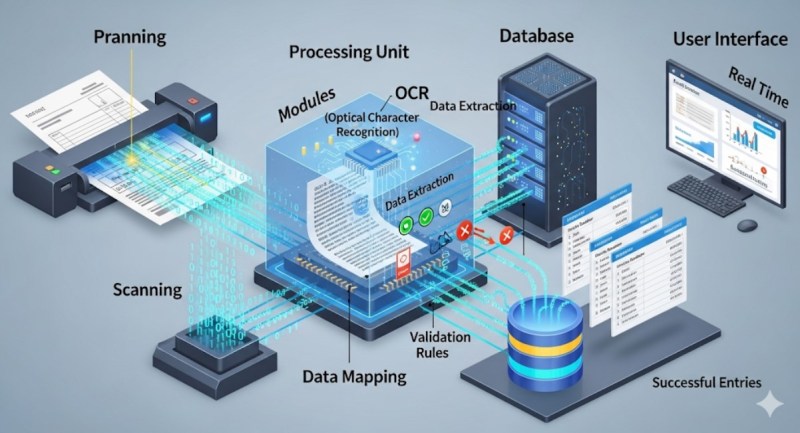
Automated data extraction—often referred to as clawer ultimate guide automated data—has evolved from niche scripting to a critical operational discipline. At its core, it automates the collection of structured or semi-structured data from websites, APIs, or databases, eliminating the bottleneck of manual entry. The term "clawer" itself nods to the organic, spider-like behavior of these systems as they traverse the web, but modern implementations go far beyond basic crawling. They incorporate machine learning for pattern recognition, proxy rotation for anonymity, and real-time data validation to ensure reliability.What sets automated data solutions apart today is their adaptability. Legacy tools relied on static rules; contemporary platforms leverage AI to handle dynamic content, such as single-page applications (SPAs) or shadow DOM elements. This shift isn’t just technical—it’s a response to the web’s increasing complexity. Businesses that treat clawer ultimate guide automated data as a one-size-fits-all process risk falling behind, while those that integrate it into broader data pipelines gain a competitive edge. The key lies in aligning extraction capabilities with specific use cases, whether it’s monitoring e-commerce inventories or aggregating financial news.
###
Historical Background and Evolution
The origins of automated data extraction trace back to the early 2000s, when developers used Perl or Python scripts to parse HTML tables—a rudimentary form of what we now call clawer ultimate guide automated data. These early tools were limited by static DOM structures and required manual updates to handle site changes. The turning point came with the rise of JavaScript frameworks like React and Angular, which introduced dynamic content loading. Suddenly, traditional parsers like BeautifulSoup couldn’t keep up, forcing the industry to adopt headless browsers (e.g., Puppeteer, Selenium) to render pages before extraction.The 2010s marked the transition from ad-hoc scraping to enterprise-grade automated data solutions. Companies like Scrapy (Python) and Octoparse democratized access, while cloud-based platforms (e.g., Apify, Bright Data) emerged to handle scalability. Today, clawer ultimate guide automated data is no longer a hacker’s toolkit but a regulated, API-first approach, with compliance features like rate limiting and user-agent spoofing baked into the design. The evolution reflects a broader trend: from extraction as a means to an end, to extraction as a strategic asset.
Table of Contents
- The Complete Overview of Clawer Ultimate Guide Automated Data
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Is clawer ultimate guide automated data legal?
- Q: How do I choose between open-source and cloud-based automated data tools?
- Q: Can clawer ultimate guide automated data handle JavaScript-heavy websites?
- Q: What’s the best way to avoid IP bans when using automated data ?
- Q: How do I ensure the data extracted is accurate?
###
Core Mechanisms: How It Works
Under the hood, clawer ultimate guide automated data systems operate through a layered architecture. The first layer is the crawler, which navigates URLs using algorithms like Breadth-First Search (BFS) or Depth-First Search (DFS). Modern crawlers prioritize efficiency by avoiding duplicate requests via bloom filters or distributed caches. The second layer handles data extraction, where selectors (CSS/XPath) or regex patterns identify target elements. For dynamic content, tools like Playwright or Cheerio simulate user interactions to trigger JavaScript execution before parsing.The final layer ensures data processing and storage. Extracted data is cleaned (e.g., removing duplicates, standardizing formats) and often enriched via APIs or third-party datasets. Storage solutions range from SQL databases for structured data to NoSQL (MongoDB) for unstructured content. What distinguishes high-performance clawer ultimate guide automated data is its ability to handle edge cases—such as CAPTCHAs (via services like 2Captcha) or IP bans (through rotating proxies)—without manual intervention.
###
Key Benefits and Crucial Impact
The value of clawer ultimate guide automated data lies in its ability to transform raw information into actionable intelligence. For e-commerce, it means real-time price tracking and inventory alerts; for finance, it enables sentiment analysis of market news. The impact isn’t just operational—it’s strategic. Companies that leverage automated data reduce costs by 40–60% compared to manual processes, while also improving decision speed. Yet, the benefits extend beyond efficiency: in industries like healthcare or legal research, clawer ultimate guide automated data accelerates compliance monitoring and due diligence.The technology’s scalability is equally transformative. A single automated data pipeline can process millions of pages daily, whereas human teams would require months to achieve the same volume. This scalability is why startups and Fortune 500 firms alike invest in clawer ultimate guide automated data—it’s not just about doing more work faster, but about unlocking insights that were previously inaccessible.
"Automated data extraction isn’t about replacing human judgment—it’s about amplifying it. The right tools don’t just collect data; they reveal patterns humans might miss." — Dr. Elena Vasquez, Data Science Lead at MIT Media Lab
Major Advantages
- Real-Time Decision Making: Clawer ultimate guide automated data pipelines deliver up-to-the-minute insights, critical for sectors like cryptocurrency or stock trading where delays cost millions.
- Cost Efficiency: Eliminates labor-intensive data entry, reducing operational overhead by up to 70% for large-scale projects.
- Compliance and Risk Mitigation: Built-in rate limiting and IP rotation minimize legal risks (e.g., violating Terms of Service or GDPR).
- Customizability: Tools like Apify or Scrapy allow developers to tailor extraction logic to specific data structures, from nested JSON to paginated tables.
- Integration Readiness: Modern automated data solutions connect seamlessly with BI tools (Tableau, Power BI) or cloud platforms (AWS, GCP), ensuring data flows into analytics workflows without friction.

Comparative Analysis
| Feature | Open-Source (e.g., Scrapy) | Cloud-Based (e.g., Apify) |
|---|---|---|
| Scalability | Limited by local infrastructure; requires custom scaling (e.g., Kubernetes). | Auto-scaling with pay-as-you-go pricing; handles global workloads. |
| Compliance | Manual configuration for rate limits/IP rotation; higher risk of bans. | Built-in compliance tools (e.g., proxy pools, CAPTCHA solving). |
| Maintenance | Developer-heavy; updates require coding knowledge. | Low-code/no-code interfaces; managed by providers. |
| Use Case Fit | Ideal for custom, long-term projects with technical teams. | Best for rapid deployment and non-technical users. |
Future Trends and Innovations
The next frontier for clawer ultimate guide automated data lies in AI-driven autonomy. Current systems rely on predefined rules; future iterations will use generative AI to infer extraction patterns from minimal examples. For instance, a model might auto-generate XPath selectors for a new e-commerce site after analyzing just a few product pages. Additionally, edge computing will reduce latency by processing data closer to its source, while blockchain-based verification could ensure data integrity in high-stakes industries like supply chain tracking.Another trend is ethical scraping, where automated data tools incorporate opt-in frameworks (e.g., data cooperatives) to respect website owners’ consent preferences. As regulations tighten (e.g., GDPR’s "scraping consent" debates), the most resilient clawer ultimate guide automated data solutions will embed compliance by design—balancing extraction needs with legal and ethical boundaries.
###

Conclusion
Clawer ultimate guide automated data is more than a technical process—it’s a strategic lever for businesses that prioritize agility and insight. The tools available today offer unprecedented flexibility, but their true power lies in how they’re applied. Whether you’re a developer building a custom scraper or a marketer analyzing competitor pricing, the right automated data approach can turn noise into clarity. The challenge isn’t just adoption; it’s integration—ensuring that extracted data aligns with broader business objectives.As the web grows more dynamic, the gap between static extraction and intelligent automation will narrow. The organizations that thrive will be those that treat clawer ultimate guide automated data not as a standalone task, but as the first step in a larger data-driven ecosystem—one where insights are extracted, analyzed, and acted upon in real time.
###
Comprehensive FAQs
Q: Is clawer ultimate guide automated data legal?
The legality depends on context. Publicly available data (e.g., product listings) is generally permissible, but scraping personal data (e.g., user profiles) may violate GDPR or CCPA. Always review robots.txt and Terms of Service, and consider using tools with built-in compliance features like Apify’s "Respectful Crawling."
Q: How do I choose between open-source and cloud-based automated data tools?
Open-source (e.g., Scrapy) is ideal for custom projects with technical teams, offering full control but requiring maintenance. Cloud-based (e.g., Bright Data) suits non-technical users or rapid deployments, with managed scalability and compliance. Assess your team’s expertise and project timeline to decide.
Q: Can clawer ultimate guide automated data handle JavaScript-heavy websites?
Yes, but it requires headless browsers like Puppeteer or Playwright. These tools render pages as a real browser would, allowing extraction from dynamic content. Libraries like Selenium are alternatives but are slower due to heavier resource usage.
Q: What’s the best way to avoid IP bans when using automated data?
Use rotating proxies (residential or datacenter) and randomize user agents. Tools like Scrapy’s DOWNLOADER_MIDDLEWARES or Apify’s proxy integration automate this. Additionally, respect robots.txt and implement delays between requests.
Q: How do I ensure the data extracted is accurate?
Implement validation rules (e.g., regex checks for phone numbers) and cross-reference with secondary sources. For dynamic data, use real-time monitoring tools to detect anomalies. Cloud platforms often include built-in data quality dashboards.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.