Tag
web scraping
-

What Are Proxies? The Hidden Architecture Powering the Digital World
Their presence is ubiquitous yet often overlooked. Behind every ad-blocker, every geo-restricted streaming workaround, and every corporate firewall sits a...
-

How Axios Post Transforms Data Journalism and API Workflows
Axios is not just another HTTP client—it’s the backbone of modern data-driven applications where precision and reliability dictate success. When developers and...
-

How to Legally Download Video of a Website (2024 Methods & Risks)
Every internet user has encountered a video worth saving—whether it’s a rare interview clip, a tutorial snippet, or a viral moment that disappears too quickly...
-

How Lists Crawlers Are Reshaping Digital Content Strategy
What makes lists crawlers uniquely powerful is their ability to interpret context within structured formats. Unlike generic web crawlers that scrape raw text...
-

The Hidden Risks and Best Free Proxy Server List for 2024
Most users turn to these tools for three core reasons: anonymity, circumvention of regional blocks, or scraping public data without detection. The problem? A...
-

Chrome Extension Download Video: The Hidden Power Tool for Digital Creators
Every minute, millions of videos vanish from the internet—deleted by platforms, taken down for copyright, or lost in algorithmic purging. For journalists...
-

The Hidden Menace: Why List Crawling Alligator Attacks Are Reshaping Data Integrity
What makes this threat particularly insidious is its dual nature. On one hand, the list crawling alligator operates as a passive harvester, silently collecting...
-

How Web Raider Content Automation Shaping Redefines Digital Publishing
What makes this evolution particularly compelling is its dual nature. On one hand, it’s a tool for efficiency—stripping away manual bottlenecks in research...
-
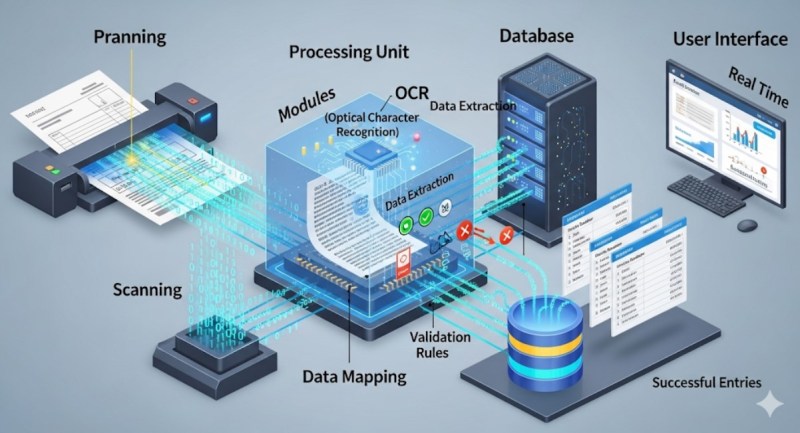
Clawer Ultimate Guide Automated Data: Mastering Web Intelligence
The right automated data framework doesn’t just scrape—it interprets. It adapts to CAPTCHAs, navigates JavaScript-rendered pages, and respects robots.txt while...