How CTE SQL Transforms Complex Queries Into Clean, Scalable Code
Modern database development demands tools that simplify intricate operations without sacrificing efficiency. Among SQL’s most powerful yet underutilized features is the CTE SQL construct—an elegant solution for organizing multi-step queries into readable, maintainable blocks. Unlike traditional subqueries that nest like Russian dolls, CTE SQL (Common Table Expressions) flattens logic into named temporary result sets, dramatically improving both developer experience and query performance. The shift toward CTE SQL reflects a broader trend: treating queries as modular components rather than monolithic statements.
The adoption of CTE SQL has grown exponentially since its introduction in SQL:1999, now a standard feature in PostgreSQL, SQL Server, Oracle, and even MySQL 8.0+. Its versatility spans from simple data filtering to recursive hierarchies, making it indispensable for analysts, data engineers, and application developers. Yet despite its ubiquity, many practitioners still overlook its full potential—whether through unfamiliarity with recursive CTE SQL or underestimating its impact on query optimization.
###
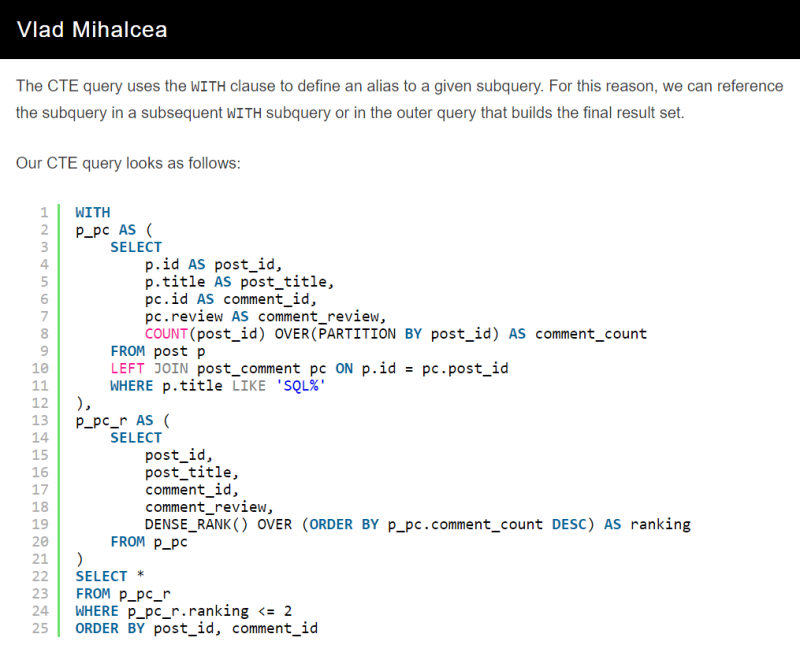
The Complete Overview of CTE SQL
CTE SQL serves as a bridge between raw SQL and structured programming paradigms. At its core, it allows developers to define temporary result sets—visible only within the enclosing query—that can be referenced multiple times, reducing redundancy. This approach mirrors programming concepts like variables or functions, but within the declarative SQL framework. The syntax, introduced via `WITH` clauses, transforms what would otherwise be a convoluted subquery into a self-documenting intermediate step.What sets CTE SQL apart is its dual role: it acts as both a readability tool and a performance enhancer. By materializing intermediate results, it enables query planners to optimize execution paths more effectively than nested subqueries. This duality explains why CTE SQL has become a cornerstone of modern SQL best practices, particularly in environments where query complexity scales with data volume.
###
Historical Background and Evolution
The origins of CTE SQL trace back to the late 1990s, when the SQL:1999 standard introduced the `WITH` clause to address the limitations of procedural SQL extensions. Before this, developers relied on temporary tables or stored procedures to manage multi-step logic, which introduced overhead and portability issues. The CTE SQL specification was designed to provide a lightweight alternative—one that didn’t require permanent storage and could be embedded directly within queries.The evolution of CTE SQL gained momentum with the addition of recursive queries in SQL:2003. This feature unlocked new use cases, such as traversing hierarchical data (e.g., organizational charts or file systems) without iterative loops. Today, CTE SQL is not just a syntactic convenience but a performance-critical tool, especially in systems like PostgreSQL, where it integrates seamlessly with advanced query planners like Citus or TimescaleDB.
Table of Contents
- The Complete Overview of CTE SQL
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can CTE SQL be used in all SQL databases?
- Q: Does CTE SQL improve query performance?
- Q: How do recursive CTE SQL queries terminate?
- Q: Can CTE SQL be used in stored procedures?
- Q: Are there performance pitfalls with CTE SQL ?
- Q: How does CTE SQL compare to window functions?
- Q: Can CTE SQL be used in distributed SQL engines?
###
Core Mechanisms: How It Works
Under the hood, CTE SQL operates by creating temporary result sets that persist only for the duration of the query. When a `WITH` clause is encountered, the database engine first evaluates all non-recursive CTEs (defined once) before proceeding to the main query. Recursive CTE SQL introduces a second phase: the engine alternates between the base case (non-recursive definition) and the recursive term (self-referencing join) until termination conditions are met.The key to efficient CTE SQL lies in its materialization strategy. Databases may choose to materialize the entire CTE upfront (for small datasets) or use incremental evaluation (for large ones). This flexibility ensures that CTE SQL remains performant across workloads, from analytical queries to real-time transaction processing.
###
Key Benefits and Crucial Impact
The adoption of CTE SQL isn’t merely a stylistic preference—it’s a strategic advantage. By encapsulating logic in named blocks, developers reduce cognitive load when debugging or modifying queries. This modularity aligns with the "single responsibility principle," where each CTE handles a distinct transformation step. The performance dividends are equally significant: CTE SQL often outperforms equivalent subqueries by enabling better optimization hints and avoiding repeated parsing of nested expressions.The impact extends beyond individual queries. Teams using CTE SQL consistently report faster development cycles, as complex operations become composable. For example, a report generating sales hierarchies can define a CTE for region aggregation once, then reuse it across multiple metrics—eliminating duplication and ensuring consistency.
"CTE SQL is the Swiss Army knife of SQL: it solves problems you didn’t know you had until you try to scale without it." — Joe Celko, SQL Expert and Author
Major Advantages
- Readability and Maintainability: Named CTEs act as documentation, making queries self-explanatory. For instance, a CTE labeled `customer_segmentation` clarifies intent better than a nested `CASE WHEN` statement.
- Performance Optimization: Databases can materialize CTEs once, avoiding redundant computations. This is particularly valuable in recursive scenarios where iterative subqueries would otherwise degrade performance.
- Modularity and Reusability: A single CTE can be referenced across multiple queries or even within the same query, reducing redundancy. This is akin to function reuse in programming.
- Support for Complex Hierarchies: Recursive CTE SQL simplifies traversals of tree-like structures (e.g., category hierarchies, bill-of-materials) without procedural code.
- Standardization Across Engines: While syntax varies slightly (e.g., Oracle’s `WITH` vs. PostgreSQL’s `WITH RECURSIVE`), the core concept is universally supported, ensuring portability.

Comparative Analysis
| Feature | CTE SQL | Traditional Subqueries | Temporary Tables |
|---|---|---|---|
| Scope | Query-level (visible only within the enclosing statement) | Query-level (nested, harder to read) | Session/database-level (persistent) |
| Performance | Optimized via materialization; avoids repeated parsing | Often less efficient due to nested evaluation | Faster for repeated use but requires DDL |
| Recursion Support | Native support (SQL:2003+) | Requires procedural extensions (e.g., PL/pgSQL) | Possible but cumbersome (manual iteration) |
| Maintainability | High (self-documenting) | Low (nested complexity) | Moderate (requires DDL management) |
Future Trends and Innovations
The trajectory of CTE SQL points toward deeper integration with machine learning and graph databases. For instance, PostgreSQL’s `WITH` clause now supports window functions and lateral joins, enabling CTE SQL to handle row-wise computations efficiently. Meanwhile, graph databases like Neo4j leverage recursive CTE SQL for traversing connected data, blurring the line between relational and graph query paradigms.Emerging trends also include CTE SQL in serverless architectures, where stateless functions benefit from the clarity and performance of temporary result sets. As data volumes grow, the ability to offload intermediate computations to CTE SQL will become a differentiator in cost-sensitive environments like cloud data warehouses.
###

Conclusion
CTE SQL is more than a syntactic sugar—it’s a paradigm shift in how developers approach query complexity. By encapsulating logic in reusable blocks, it aligns SQL with modern software engineering principles, where modularity and performance are non-negotiable. The future of CTE SQL lies in its adaptability: whether optimizing analytical queries or powering real-time applications, its role will expand as databases evolve.For practitioners, the takeaway is clear: CTE SQL is not optional but essential. Ignoring it risks falling behind in both productivity and performance, while embracing it unlocks queries that are not just functional but elegant.
###
Comprehensive FAQs
Q: Can CTE SQL be used in all SQL databases?
A: While the core `WITH` clause is standard (SQL:1999), recursive CTE SQL (via `WITH RECURSIVE`) was added in SQL:2003. Modern engines like PostgreSQL, SQL Server, Oracle, and MySQL 8.0+ fully support it, but older versions (e.g., MySQL 5.7) may require workarounds like stored procedures.
Q: Does CTE SQL improve query performance?
A: Yes, but context matters. CTE SQL can outperform nested subqueries by reducing parsing overhead and enabling materialization. However, for simple queries, the performance gain may be negligible. Always benchmark against alternatives like temporary tables.
Q: How do recursive CTE SQL queries terminate?
A: Recursive CTE SQL terminates when the recursive term returns no rows (i.e., the `UNION ALL` condition fails). This is controlled by the base case (non-recursive part) and the termination logic in the recursive term, which must eventually exclude rows from further iterations.
Q: Can CTE SQL be used in stored procedures?
A: Absolutely. CTE SQL is fully compatible with stored procedures in most databases. In fact, it’s often preferred over temporary tables within procedures to avoid DDL overhead and improve readability.
Q: Are there performance pitfalls with CTE SQL?
A: Yes. Overusing CTE SQL with large datasets can consume excessive memory if not materialized efficiently. Additionally, recursive queries without proper termination conditions may run indefinitely. Always test with `EXPLAIN ANALYZE` to verify execution plans.
Q: How does CTE SQL compare to window functions?
A: CTE SQL and window functions serve different purposes. CTE SQL is for multi-step transformations, while window functions handle row-wise calculations (e.g., rankings, moving averages). They often complement each other—for example, a CTE might filter data before applying window functions.
Q: Can CTE SQL be used in distributed SQL engines?
A: Yes, but with caveats. Engines like Google BigQuery or Snowflake support CTE SQL natively, but distributed execution may require partitioning strategies to avoid shuffling intermediate results across nodes. Always review the engine’s documentation for optimizations.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.