How `git add .` Transforms Your Workflow: The Command Every Developer Should Know
The first time you encounter `git add .` in a terminal, it feels like a shortcut—too good to be true. A single keystroke to stage every modified, deleted, or new file in your working directory? It’s tempting to use it everywhere, but that’s a mistake. The command’s simplicity masks a nuanced interplay between Git’s staging area, file states, and commit granularity. Developers who treat `git add .` as a one-size-fits-all solution often find themselves debugging unexpected merges or staged files they didn’t intend to include.
What separates the efficient from the reactive is understanding when to use `git add .` and when to stage files selectively. The command’s power lies in its ability to streamline workflows—yet its misuse can introduce chaos into collaborative projects. For instance, staging a partially written feature branch alongside unrelated bug fixes might seem harmless until a teammate’s `git pull` overwrites local changes. The line between convenience and risk is thin, and the stakes grow higher in teams where branching strategies like GitFlow or Trunk-Based Development demand precision.
The truth is, `git add .` isn’t just a command—it’s a philosophical choice about how you manage change. Should you embrace its brute-force efficiency, or should you wield finer-grained staging tools like `git add -p` for surgical control? The answer depends on context: a solo project with trivial changes might benefit from the command’s speed, while a shared repository with complex dependencies could suffer from its lack of specificity.
The Complete Overview of `git add .`
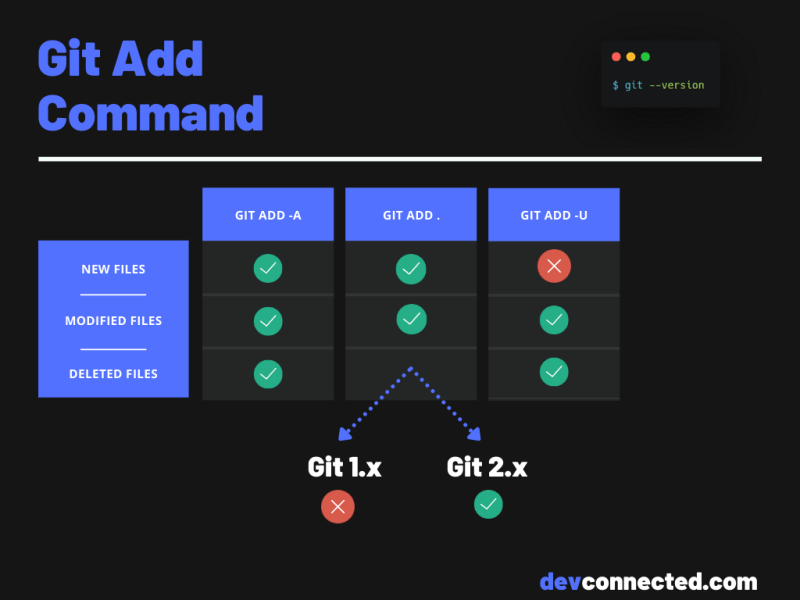
At its core, `git add .` is a shorthand for staging all changes in the working directory. Unlike `git addHowever, the command’s simplicity is both its strength and its Achilles’ heel. While it excels in scenarios like rapid prototyping or staging entire feature implementations, it lacks the granularity needed for incremental commits. For example, a developer fixing a critical bug might accidentally stage unrelated CSS tweaks meant for a future sprint, leading to a commit that mixes concerns. The lack of explicit file selection forces users to either rely on memory or post-commit cleanup, which is rarely ideal.
Historical Background and Evolution
The concept of staging changes predates `git add .` by decades, rooted in the early days of version control systems like CVS and Subversion. These systems introduced the idea of a "working copy" and a "repository," where changes were staged before being committed. Git, created by Linus Torvalds in 2005, inherited this staging area but reimagined it as a first-class citizen in the workflow. The `git add` command itself emerged as part of Git’s core functionality, designed to give developers fine-grained control over what changes were included in a commit.The introduction of `.` as a wildcard in `git add` was a natural evolution—developers needed a quick way to stage all changes without manually listing each file. This became especially valuable as projects grew in complexity, with directories containing hundreds or thousands of files. The command’s adoption was further accelerated by the rise of GitHub and collaborative coding, where speed and simplicity in staging became non-negotiable. Over time, variations like `git add -A` (which stages all changes, including ignored files) and `git add --patch` (`-p`) emerged to address specific pain points, but `git add .` remained the default choice for most use cases.
Core Mechanisms: How It Works
Under the hood, `git add .` triggers a series of operations in Git’s plumbing. First, Git scans the working directory recursively, comparing each file’s state against its version in the index (staging area). For modified files, it checks whether the changes are staged or unstaged; for new files, it verifies they aren’t listed in `.gitignore`. Deleted files are marked as such in the index. Once the scan completes, Git updates the index to reflect these changes, effectively "staging" them for the next commit.Table of Contents
- The Complete Overview of `git add .`
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between `git add .` and `git add -A`?
- Q: Can `git add .` stage files in subdirectories?
- Q: What happens if I run `git add .` after deleting a file?
- Q: Is `git add .` safe for collaborative projects?
- Q: How can I undo a `git add .` before committing?
- Q: Does `git add .` work with Git LFS-tracked files?
- Q: Can I use `git add .` in a bare repository?
- Q: What’s the fastest way to stage all changes except one file?
The command’s behavior can be fine-tuned with flags. For instance, `git add -u` stages only modified and deleted files (excluding new untracked files), while `git add -N` stages files but doesn’t update their working tree state (useful for dry runs). The `.` in `git add .` refers to the current directory, but it can be replaced with a path (e.g., `git add src/`) to stage changes in a specific subdirectory. This flexibility makes the command adaptable to various project structures, though it also introduces room for error if paths are mispecified.
Key Benefits and Crucial Impact
The primary appeal of `git add .` lies in its ability to eliminate repetitive typing. In a project with dozens of modified files, manually staging each one would be time-consuming and error-prone. The command reduces this overhead to a single keystroke, making it indispensable for developers working on large codebases or frequent iterations. Beyond speed, it fosters consistency—every developer on a team can use the same command to stage changes, reducing variability in commit practices.However, the command’s impact extends beyond mere convenience. By staging all changes at once, it encourages a "commit often" mindset, which aligns with Git’s philosophy of small, incremental updates. This practice reduces the risk of large, unwieldy commits that are difficult to review or revert. For solo developers, it simplifies the workflow by removing the need for intermediate staging decisions. Yet, in collaborative environments, its lack of specificity can lead to unintended consequences, such as staging files that shouldn’t be committed yet.
"The staging area is where Git’s power and flexibility meet. `git add .` is a sledgehammer—useful for demolition, but not for precision work."
— Linus Torvalds (paraphrased)
Major Advantages
- Speed: Stages all changes in milliseconds, ideal for rapid development cycles.
- Simplicity: Eliminates the need to list individual files, reducing cognitive load.
- Consistency: Standardizes staging across teams, minimizing workflow discrepancies.
- Atomicity: Ensures all changes are staged together, which can be useful for feature branches.
- Scalability: Works efficiently even in large repositories with thousands of files.

Comparative Analysis
| Command | Use Case |
|---|---|
git add . |
Staging all changes in the current directory (modified, new, deleted). Best for bulk operations. |
git add -p |
Interactive staging—lets you review and select changes line by line. Ideal for selective commits. |
git add |
Staging a single file. Useful for granular control over specific changes. |
git add -A |
Stages all changes, including ignored files. Rarely recommended unless intentional. |
Future Trends and Innovations
As Git continues to evolve, the role of `git add .` may shift in response to new workflow demands. Tools like Git LFS (Large File Storage) and partial clones are pushing Git’s boundaries, and commands like `git add` might integrate more tightly with these features. For example, future versions of Git could automatically exclude LFS-tracked files from `git add .` unless explicitly requested, reducing the risk of bloated repositories.Another trend is the rise of AI-assisted Git tools, which could analyze staged changes and suggest optimizations—such as splitting commits or flagging potential conflicts. While `git add .` itself won’t change drastically, its context within the broader Git ecosystem will expand. Developers may see more hybrid approaches, where the command is used in conjunction with AI-driven staging suggestions or automated commit message generation.

Conclusion
`git add .` is more than a shortcut—it’s a reflection of how developers balance speed and control. Its strength lies in its ability to handle bulk operations efficiently, but its limitations remind us that no tool is universally applicable. The key to mastering it is context: knowing when to use it for rapid prototyping and when to switch to `git add -p` for surgical precision. As Git matures, the command will likely remain a staple, but its integration with newer features will redefine its role in modern workflows.Ultimately, the command’s enduring relevance stems from its alignment with Git’s core principles: simplicity, flexibility, and efficiency. Whether you’re a solo developer or part of a distributed team, understanding `git add .` isn’t just about using a command—it’s about embracing a mindset of intentional change management.
Comprehensive FAQs
Q: What’s the difference between `git add .` and `git add -A`?
A: `git add .` stages all changes in the current directory and subdirectories, excluding ignored files by default. `git add -A` (or `--all`) stages all changes, including ignored files. Use `-A` only if you intentionally want to include ignored files.
Q: Can `git add .` stage files in subdirectories?
A: Yes. The `.` refers to the current directory and all its subdirectories recursively. To stage changes in a specific subdirectory, use `git add path/to/directory/`.
Q: What happens if I run `git add .` after deleting a file?
A: The deleted file is staged as a deletion. To confirm, run `git status`—it will show the file under "Changes to be committed" with a "deleted" status.
Q: Is `git add .` safe for collaborative projects?
A: It depends. While safe for solo work, it can accidentally stage unrelated changes in shared repositories. Always review `git status` after staging to avoid committing unintended files.
Q: How can I undo a `git add .` before committing?
A: Use `git reset` to unstage all changes: `git reset`. To unstage specific files, use `git reset HEAD
Q: Does `git add .` work with Git LFS-tracked files?
A: By default, yes—it stages LFS-tracked files like any other. However, LFS files are large, so staging them unnecessarily can slow down operations. Use `git lfs track` to manage them explicitly.
Q: Can I use `git add .` in a bare repository?
A: No. Bare repositories (`git init --bare`) lack a working directory, so `git add .` will fail. Use it only in repositories with a working tree.
Q: What’s the fastest way to stage all changes except one file?
A: Stage everything first with `git add .`, then unstage the unwanted file: `git reset HEAD
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.