How Git Clone Transforms Collaboration in Modern Software Development
The first time a developer encounters the `git clone` command, it feels like unlocking a vault of possibilities. A single line of text—`git clone [repository-url]`—transforms a remote repository into a local workspace, bridging the gap between abstract code and tangible development. This isn’t just replication; it’s the foundation of modern collaboration, where distributed teams synchronize effort without friction. Yet, beneath its simplicity lies a sophisticated interplay of network protocols, cryptographic hashing, and distributed architecture that ensures integrity, speed, and scalability.
For enterprises relying on GitHub, GitLab, or Bitbucket, the act of cloning a repository isn’t merely procedural—it’s strategic. A poorly configured clone can bottleneck workflows, while an optimized one accelerates feature development by minutes per engineer. The command’s versatility extends beyond developers: DevOps engineers use it to spin up infrastructure-as-code environments, data scientists replicate datasets, and even non-technical stakeholders inspect project structures. Its ubiquity masks the fact that `git clone` is a microcosm of Git’s philosophy: decentralization, efficiency, and reproducibility.
But how does it actually work? The answer lies in the interplay between Git’s object database, the shallow clone optimization, and the sparse checkout feature—each designed to address a specific pain point in real-world usage. Whether you’re debugging a legacy monorepo or deploying a microservice, understanding these mechanics isn’t just technical curiosity; it’s a competitive advantage. Below, we dissect the command’s evolution, its internal mechanics, and why it remains indispensable in an era of cloud-native development.
The Complete Overview of Git Clone
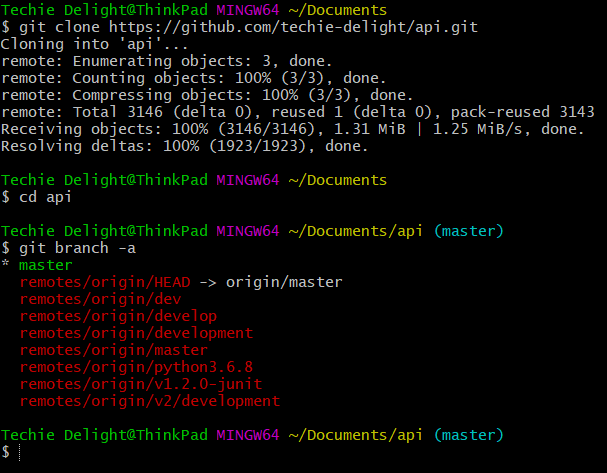
The `git clone` command is the gateway to participation in any Git-managed project, yet its role is often underestimated. At its core, it’s a network-aware operation that fetches an entire repository—including its commit history, branches, tags, and submodules—from a remote server and mirrors it locally. What distinguishes it from a simple file download is Git’s use of a content-addressable filesystem: every file, commit, and tree object is stored with a cryptographic hash (SHA-1) as its identifier. This ensures that even if filenames change, the underlying data remains verifiable and tamper-proof.
Modern implementations of `git clone` leverage smart HTTP/SSH protocols to minimize bandwidth usage. Instead of transferring every object in the repository, Git employs a packfile format that compresses and delta-encodes objects, reducing transfer sizes by up to 70%. This efficiency is critical for large repositories (e.g., the Linux kernel or Android’s AOSP), where a naive clone could consume gigabytes of bandwidth. Additionally, the `--depth` flag enables shallow cloning, fetching only the most recent commits—a lifesaver for CI/CD pipelines where full history isn’t needed.
Historical Background and Evolution
The concept of cloning a repository emerged in the early days of Git’s design, when Linus Torvalds prioritized decentralized workflows over centralized version control systems like Subversion. The first implementation in Git 0.99 (2005) was rudimentary: it used a combination of `rsync` and custom protocols to replicate repositories. By Git 1.5 (2007), the introduction of the smart HTTP protocol revolutionized cloning by enabling efficient server-side push/pull operations over standard web ports, bypassing firewall restrictions.
Table of Contents
- The Complete Overview of Git Clone
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can I clone only a specific branch or tag?
- Q: Why does `git clone` take longer than expected?
- Q: How does `git clone --reference` improve performance?
- Q: Is there a way to clone a repository without its history?
- Q: What’s the difference between `git clone` and `git init` + `git remote add`?
- Q: Can I clone a private repository without credentials?
- Q: How do I clone a repository with submodules?
- Q: Why does `git clone` fail with "Repository not found" or "Permission denied"?
- Q: Can I clone a repository to a non-default directory?
- Q: How does Git handle large files in `git clone`?
A pivotal moment came with Git 1.8.5 (2013), when the `--reference` option was added, allowing developers to clone a repository using another local repository as a reference cache. This reduced redundant downloads when multiple teams worked on similar codebases. Later, Git 2.23 (2019) introduced partial clone support, enabling selective object fetching via --filter=blob:none, a game-changer for repositories with massive binary assets (e.g., game engines or media projects). These evolutions reflect Git’s adaptive nature—constantly optimizing for real-world constraints.
Core Mechanisms: How It Works
When you execute `git clone [url]`, Git initiates a multi-stage process. First, it negotiates with the remote server to determine the repository’s capabilities (e.g., whether it supports shallow clones or multi-pack-index). The server then sends a packfile containing all necessary objects, which Git decompresses and stores in its local object database (/.git/objects). Concurrently, Git reconstructs the repository’s structure by reading the HEAD reference, initializing branches, and setting up the working directory.
The command’s efficiency hinges on two key optimizations: delta compression and object reuse. Delta compression reduces storage by storing only differences between similar objects (e.g., consecutive commits). Object reuse avoids redundant storage of identical files across branches or submodules. For example, if two branches share 90% of their history, Git clones only the divergent commits. This is why cloning a repository with 10,000 commits might take seconds rather than minutes—Git’s design anticipates real-world usage patterns.
Key Benefits and Crucial Impact
The `git clone` command is more than a utility; it’s a force multiplier for development teams. By enabling instant, verifiable replication of codebases, it eliminates the "works on my machine" problem, ensuring consistency across environments. For open-source projects, it democratizes contribution by lowering the barrier to entry: a single command grants access to years of development history, documentation, and community discussions. Even in proprietary settings, cloning streamlines onboarding, allowing new hires to sync with the latest code in minutes rather than days.
Beyond collaboration, `git clone` underpins modern DevOps practices. Infrastructure-as-code repositories (e.g., Terraform modules) rely on cloning to deploy identical environments. Machine learning pipelines use it to replicate datasets or model weights. The command’s role in CI/CD is equally critical: every pull request trigger, every automated test suite, begins with a clone. Without it, the agility of cloud-native development would stall.
"Git clone isn’t just copying files—it’s copying the entire intellectual context of a project: its decisions, its experiments, and its evolution. That’s why it’s the most powerful command in version control."
— Linus Torvalds (Git Creator, in a 2015 interview)
Major Advantages
- Instant Local Replication: Transfers the entire repository (or a subset) in seconds, including branches, tags, and submodules, without manual setup.
- Data Integrity: Uses cryptographic hashing (SHA-1) to ensure no corruption occurs during transfer, even over unreliable networks.
- Bandwidth Efficiency: Smart protocols and packfiles reduce transfer sizes by 50–70%, critical for large repositories (e.g., >1GB).
- Flexible Customization: Supports shallow clones (
--depth), partial checks (--filter), and sparse checkouts (--sparse) to optimize for specific use cases. - Cross-Platform Compatibility: Works seamlessly across Linux, macOS, and Windows (via Git Bash or WSL), with support for HTTPS, SSH, and Git protocols.

Comparative Analysis
| Feature | Git Clone | Alternative (e.g., SVN Checkout) |
|---|---|---|
| Transfer Method | Delta-encoded packfiles over HTTP/SSH/Git | Full file copies over HTTP/DAV (no delta compression) |
| History Handling | Full commit history by default; supports shallow clones | Limited to latest revision (no native history cloning) |
| Network Overhead | Optimized for large repos (e.g., Linux kernel: ~12GB → ~3GB) | High overhead for binary-heavy projects |
| Offline Capabilities | Full repository available locally; no server dependency | Requires server connectivity for updates |
Future Trends and Innovations
The next frontier for `git clone` lies in adaptive fetching, where Git dynamically prioritizes objects based on usage patterns. Imagine a clone that automatically skips unused branches or fetches only the code paths relevant to your current task—this is already in experimental stages via partial clone filters. Another trend is federated repositories, where Git could clone only the portions of a monorepo relevant to your team, reducing storage bloat. For cloud-native workflows, Git LFS integration will become standard, enabling seamless cloning of large files (e.g., datasets, binaries) without bloating the main repository.
Security is another evolving concern. As supply-chain attacks target open-source dependencies, Git may introduce verified cloning, where repositories include cryptographic proofs of authenticity (e.g., sigstore signatures). Tools like cosign are already paving the way for this. Meanwhile, the rise of ephemeral environments (e.g., GitHub Codespaces) will push `git clone` to handle transient, disposable workspaces with minimal overhead. The command’s future isn’t just about speed—it’s about intelligence and security.
Conclusion
The `git clone` command is a testament to Git’s brilliance: it solves a deceptively simple problem—replicating a repository—with a solution that’s deceptively complex. Its evolution mirrors the needs of modern development: from Linus Torvalds’ early focus on decentralization to today’s emphasis on scalability and security. For developers, it’s the first step in contributing to a project; for DevOps teams, it’s the backbone of reproducible infrastructure; for open-source maintainers, it’s the gateway to global collaboration. Without it, the velocity of software development would grind to a halt.
Yet, its power isn’t just in what it does, but in how it enables. By making repositories portable, verifiable, and efficient, `git clone` reduces friction between ideas and execution. As development becomes more distributed—across cloud regions, edge devices, and AI-driven workflows—the command’s role will only grow. The next time you run `git clone`, remember: you’re not just copying code. You’re inheriting a lineage of innovation, and setting the stage for the next iteration.
Comprehensive FAQs
Q: Can I clone only a specific branch or tag?
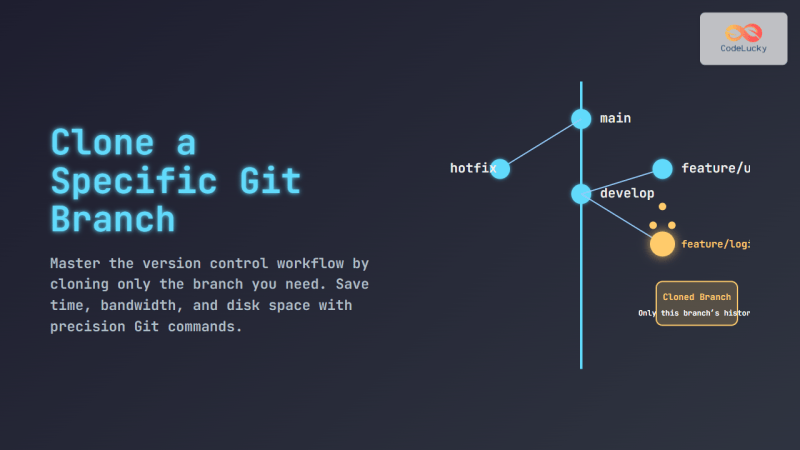
A: Yes. Use the --branch flag to clone a single branch (e.g., git clone --branch feature/x repo-url) or the --single-branch flag to avoid fetching all branches. For tags, clone the repository normally, then checkout the tag with git checkout tags/v1.0.
Q: Why does `git clone` take longer than expected?
A: Several factors can slow it down: large packfiles (common in binary-heavy repos), network latency, or server-side limitations (e.g., rate limits). Use --depth 1 for shallow clones, or check if the remote supports --filter=blob:none to exclude large files. Tools like git-filter-repo can pre-process repositories for faster cloning.
Q: How does `git clone --reference` improve performance?
A: The --reference flag allows Git to reuse objects from an existing local repository (e.g., a shared cache). This avoids redundant downloads when multiple developers clone the same repo. For example, git clone --reference /path/to/cache repo-url will fetch only missing objects, reducing bandwidth by up to 90% in some cases.
Q: Is there a way to clone a repository without its history?
A: Yes. Use git clone --depth 1 to fetch only the latest commit. For a completely history-less clone, you can use git clone --depth 1 && git reset --hard HEAD~1, though this removes all branch references. Note that this breaks some Git features (e.g., git blame) that rely on history.
Q: What’s the difference between `git clone` and `git init` + `git remote add`?
A: git clone is a shortcut that combines git init, git remote add, and git fetch --all in one step. It also sets up the local branches and working directory. Using git init + git remote add manually gives you more control (e.g., to customize the remote name), but requires additional steps to fetch the repository.
Q: Can I clone a private repository without credentials?
A: No. Private repositories require authentication. For HTTPS, Git will prompt for credentials or use a stored token (e.g., from git config --global credential.helper). For SSH, ensure your SSH key is added to the remote’s authorized_keys. Some platforms (e.g., GitHub) support personal access tokens (PATs) instead of passwords.
Q: How do I clone a repository with submodules?
A: Use git clone --recurse-submodules to automatically initialize and update all submodules. Without this flag, you’ll need to run git submodule update --init --recursive afterward. For large repos, consider --depth 1 --recurse-submodules to limit history while still fetching submodules.
Q: Why does `git clone` fail with "Repository not found" or "Permission denied"?
A: This typically indicates one of three issues: (1) the URL is incorrect (verify with git remote -v), (2) you lack permissions (check repository visibility settings), or (3) the remote server is unreachable (test with ping or curl -v). For GitHub, ensure you’re using the correct format (e.g., https://github.com/user/repo.git or git@github.com:user/repo.git).
Q: Can I clone a repository to a non-default directory?
A: Yes. Specify the target directory as the last argument: git clone repo-url /custom/path. This creates the repository inside /custom/path instead of the current directory. Note that the path must not already exist unless you use --separate-git-dir.
Q: How does Git handle large files in `git clone`?
A: By default, Git stores large files (e.g., >100MB) inefficiently, bloating the repository. Solutions include: (1) Git LFS (for binaries like datasets), (2) --filter=blob:none (to exclude blobs), or (3) git-annex for external storage. Always avoid committing large files directly to the main repo.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.