How Python Reverse String Transforms Data Processing in Modern Development
Python’s ability to manipulate strings with precision has cemented its dominance in data-driven applications. Among its most fundamental yet powerful operations is the reverse string function—a technique that flips character sequences to unlock efficiency in parsing, encryption, and text analysis. Whether you’re processing log files, validating palindromes, or optimizing search algorithms, understanding how to reverse strings in Python isn’t just a coding skill; it’s a strategic advantage.
The elegance of Python’s reverse string implementations lies in their versatility. From built-in methods like slicing (`[::-1]`) to iterative approaches, developers wield multiple tools to achieve the same result with varying trade-offs in readability and performance. This duality reflects Python’s design philosophy: simplicity for rapid prototyping and flexibility for high-performance scenarios. Yet beneath the surface, the mechanics of reversing strings reveal deeper insights into memory management, Unicode handling, and algorithmic complexity—topics often overlooked in introductory tutorials.
What separates a novice from an expert isn’t just knowing how to reverse a string, but when and why to apply it. A poorly optimized reverse operation can cripple performance in large-scale text processing, while a well-placed string reversal can simplify complex logic. This article dissects the Python reverse string ecosystem—its historical roots, core mechanics, and practical impact—while equipping you with the knowledge to leverage it effectively.

The Complete Overview of Python Reverse String
Python’s reverse string functionality exemplifies the language’s balance between accessibility and power. At its core, reversing a string involves iterating backward through its characters or employing slicing syntax to invert the sequence. While this may seem trivial for small strings, the implications scale dramatically in applications handling terabytes of text, where even micro-optimizations matter. The operation’s simplicity belies its role in foundational tasks: from reversing user input for validation to preprocessing data for machine learning pipelines.The Python reverse string paradigm extends beyond basic syntax. Developers must consider edge cases—such as Unicode grapheme clusters (where a single character may span multiple code points)—and performance bottlenecks in loops. Modern Python versions (3.7+) introduce optimizations like the `reversed()` function and memory-efficient generators, but legacy codebases may still rely on older methods. This duality underscores a critical tension: maintaining backward compatibility while adopting cutting-edge techniques.
Historical Background and Evolution
The concept of reversing strings predates Python itself, emerging in early programming languages like Fortran and C as a way to manipulate text buffers. By the time Python was conceived in the late 1980s, string reversal had already become a staple in algorithmic challenges, particularly in competitive programming. Guido van Rossum’s design choices for Python—prioritizing readability—led to the adoption of slicing (`[::-1]`) as the idiomatic way to reverse strings, a feature introduced in Python 2.0 (2000). This approach combined conciseness with efficiency, leveraging Python’s underlying memory model to avoid explicit loops.Over time, the Python reverse string landscape evolved alongside the language’s growth. Python 3’s strict Unicode support forced developers to reconsider how strings were reversed, as grapheme clusters (e.g., emojis or accented characters) could break naive implementations. The introduction of the `reversed()` function in Python 3.3 provided a more explicit alternative, though slicing remained the preferred method for its brevity. Today, the reverse string operation is a microcosm of Python’s broader evolution: a blend of historical pragmatism and modern optimization.
Core Mechanisms: How It Works
Under the hood, Python’s reverse string methods exploit the language’s dynamic typing and memory management. The slicing technique (`[::-1]`) creates a new string by stepping backward through the original, a process handled efficiently by Python’s interpreter. This approach is O(n) in time complexity, where n is the string length, and O(n) in space due to the creation of a copy. For small strings, this overhead is negligible, but in large-scale applications, alternatives like generators or in-place modifications (where possible) may be preferable.Table of Contents
- The Complete Overview of Python Reverse String
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does slicing (`[::-1]`) work for reversing strings in Python?
- Q: How does Python handle Unicode characters when reversing strings?
- Q: Is there a performance difference between `[::-1]` and `reversed()` + `join()`?
- Q: Can I reverse a string in-place in Python?
- Q: What are common pitfalls when reversing strings in Python?
- Q: How can I reverse a string without using built-in methods?
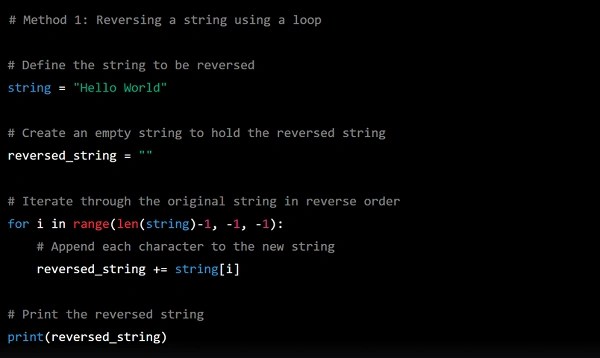
Iterative methods, such as reversing a string using a loop, offer more control but sacrifice readability. For example:
```python
reversed_str = ""
for char in original_str:
reversed_str = char + reversed_str
```
This approach is O(n²) in time due to string concatenation in each iteration, making it inefficient for long strings. Modern Python mitigates this with optimizations like small-string interning, but the lesson remains: Python reverse string operations must align with the problem’s scale and constraints.
Key Benefits and Crucial Impact
The reverse string operation is more than a syntactic trick—it’s a building block for robust data processing. In text analysis, reversing strings simplifies tasks like checking palindromes or validating symmetric patterns. In cryptography, it’s a foundational step in algorithms like the Vigenère cipher. Even in mundane tasks, such as reversing log entries for chronological sorting, the operation’s efficiency can mean the difference between a lagging system and a high-performance pipeline.Beyond functionality, Python reverse string techniques foster cleaner code. By abstracting low-level iteration, Python allows developers to express intent clearly. For instance, reversing a string to normalize input or preprocess data reduces cognitive load, enabling teams to focus on higher-level logic. The ripple effects extend to collaboration: a well-documented reverse string operation can serve as a reusable utility across projects, reducing redundancy.
"Elegance is not a dispensable luxury but a key component of software design. The right tool—whether slicing or iteration—can turn a clunky solution into a masterpiece of conciseness." — Guido van Rossum (Python’s Creator, on Design Philosophy)
Major Advantages
- Performance Efficiency: Slicing (`[::-1]`) is optimized at the C level in Python’s interpreter, making it faster than manual loops for most use cases.
- Readability: A single line of code (`reversed_str = original_str[::-1]`) conveys the operation’s intent clearly, reducing maintenance overhead.
- Unicode Safety: Modern Python versions handle grapheme clusters correctly when reversing, avoiding corruption of multi-byte characters.
- Memory Optimization: Generators and `reversed()` can process large strings without loading the entire reversed sequence into memory.
- Versatility: The operation integrates seamlessly with other Python features, such as list comprehensions or regular expressions, for advanced text processing.
Comparative Analysis
| Method | Pros and Cons |
|---|---|
[::-1] (Slicing) |
Fast, concise, but creates a new string in memory. Best for small-to-medium strings. |
reversed() + join() |
Memory-efficient for large strings (returns an iterator), but slightly slower due to two passes. |
| Manual Loop | Full control over logic, but O(n²) time complexity and verbose. Avoid for performance-critical code. |
Third-Party Libraries (e.g., numpy) |
Useful for array-like operations, but overkill for simple string reversal. |
Future Trends and Innovations
As Python continues to evolve, the reverse string operation will likely see refinements in Unicode handling and performance. The rise of Just-In-Time (JIT) compilation in libraries like Numba could further optimize slicing operations, making them competitive with manual loops. Additionally, the growing emphasis on memory safety in Python (e.g., via the `memoryview` protocol) may introduce new ways to reverse strings in-place, reducing memory overhead for large datasets.The broader impact of Python reverse string techniques lies in their role within larger ecosystems. As natural language processing (NLP) and data science expand, string reversal will remain a critical primitive for tasks like text normalization, tokenization, and even adversarial attacks in security. Developers who master these fundamentals will be better positioned to innovate in fields where text manipulation is king.

Conclusion
Python’s reverse string functionality is a testament to the language’s ability to balance simplicity with power. Whether you’re reversing a password for hashing, cleaning up user input, or preprocessing data for analysis, the operation’s versatility makes it indispensable. The key to leveraging it effectively lies in understanding its trade-offs: speed versus memory, readability versus control, and modern optimizations versus legacy constraints.As you integrate Python reverse string techniques into your workflow, remember that the goal isn’t just to flip characters—it’s to flip your approach to problem-solving. By mastering these fundamentals, you’ll unlock cleaner code, better performance, and a deeper appreciation for Python’s design philosophy.
Comprehensive FAQs
Q: Why does slicing (`[::-1]`) work for reversing strings in Python?
A: Python’s slicing syntax `[start:stop:step]` defaults to `step=1` when omitted. Using `[::-1]` sets the step to `-1`, iterating backward through the string. This is optimized at the interpreter level for efficiency.
Q: How does Python handle Unicode characters when reversing strings?
A: In Python 3, strings are Unicode by default, and slicing (`[::-1]`) correctly reverses grapheme clusters (e.g., emojis or accented characters). However, naive loops may fail if they split surrogate pairs incorrectly. Always use slicing or `reversed()` for safety.
Q: Is there a performance difference between `[::-1]` and `reversed()` + `join()`?
A: Yes. Slicing is generally faster for small strings because it’s a single C-level operation. For large strings, `reversed()` + `join()` is more memory-efficient as it uses an iterator, but it requires two passes (one for reversal, one for joining). Benchmark for your use case.
Q: Can I reverse a string in-place in Python?
A: No. Python strings are immutable, so any reversal creates a new object. For mutable sequences (e.g., lists), use `[::-1]` or `reverse()` method. Strings must be converted to lists first if in-place modification is needed.
Q: What are common pitfalls when reversing strings in Python?
A: Pitfalls include:
- Assuming slicing works for all Unicode (test with emojis or combining characters).
- Using loops for large strings (O(n²) time).
- Ignoring memory constraints (slicing duplicates the string).
Q: How can I reverse a string without using built-in methods?
A: You can use recursion or iterative approaches:
def reverse_string(s):
However, this is less efficient than slicing due to Python’s recursion limits and string concatenation overhead.
return s if len(s) <= 1 else reverse_string(s[1:]) + s[0]
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.