Mastering Python String Replace: The Definitive Guide to Text Transformation
Python’s string manipulation capabilities are foundational for any developer working with text data, from cleaning datasets to parsing user input. The `str.replace()` method stands as one of the most versatile tools in this arsenal, offering precision and efficiency for replacing substrings within strings. Unlike brute-force approaches or regex-heavy solutions, this built-in function provides a clean, readable syntax that handles most use cases without unnecessary complexity. Yet, beneath its simplicity lies a nuanced system capable of addressing edge cases—from case sensitivity to memory constraints—that demand deeper understanding.
The method’s ubiquity stems from its balance between performance and clarity. Developers across domains—from web scraping to natural language processing—rely on `python string replace` operations to sanitize input, standardize formats, or extract meaningful patterns. Its integration with other string methods (like `split()` or `join()`) further amplifies its utility, making it a cornerstone of Python’s text-processing ecosystem. However, misuse can lead to subtle bugs, particularly when dealing with Unicode, overlapping matches, or large-scale replacements.
While alternatives like regular expressions offer more advanced pattern matching, `str.replace()` excels in scenarios where direct substring replacement suffices. Its deterministic behavior and minimal overhead make it ideal for performance-critical applications, though understanding its limitations—such as the inability to handle overlapping matches—is crucial for robust implementations.
The Complete Overview of Python String Replace
Python’s `str.replace()` method is designed for simplicity and efficiency, allowing developers to replace occurrences of a substring within a string with another substring. The method signature, `str.replace(old, new[, count])`, accepts three parameters: the substring to be replaced (`old`), the replacement string (`new`), and an optional `count` parameter that limits the number of replacements. When omitted, `count` defaults to `-1`, meaning all occurrences are replaced. This design prioritizes clarity while accommodating flexibility for specific use cases.Under the hood, `python string replace` operations leverage Python’s string interning and memory management to optimize performance. For ASCII strings, the method operates in linear time, O(n), where n is the length of the string. However, Unicode strings introduce additional overhead due to variable-width characters, which can impact performance in large-scale text processing. Developers must weigh the trade-offs between readability and efficiency, especially when working with multilingual or encoded text.
Historical Background and Evolution
The `str.replace()` method traces its origins to Python’s early design philosophy, which emphasized readability and ease of use. Introduced in Python 1.0 (1991), the method was part of a broader push to standardize string operations across the language. Early implementations were straightforward, focusing on basic substring replacement without advanced features like regex support. As Python evolved, so did its string handling capabilities, with later versions introducing methods like `str.translate()` for more complex transformations.The method’s enduring relevance reflects its alignment with Python’s core principles: explicit over implicit and simple over complex. Unlike languages that require manual iteration or external libraries for basic replacements, Python’s built-in `python string replace` function abstracts away low-level details, allowing developers to focus on logic rather than implementation. This design choice has cemented its role in Python’s standard library, where it remains a go-to tool for text manipulation.
Core Mechanisms: How It Works
At its core, `str.replace()` performs a linear scan of the input string, comparing each substring of length `len(old)` to the target substring. When a match is found, the method replaces it with `new` and continues scanning from the next character. The optional `count` parameter introduces a constraint: if specified, the method stops after replacing `count` occurrences, regardless of remaining matches. This behavior is particularly useful for partial replacements or when only the first few instances need modification.Table of Contents
- The Complete Overview of Python String Replace
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can `str.replace()` handle overlapping matches?
- Q: How does `str.replace()` perform with Unicode?
- Q: Is `str.replace()` case-sensitive?
- Q: What happens if `old` is not found in the string?
- Q: Can `str.replace()` modify strings in-place?
- Q: How does `count` affect performance?
- Q: Are there memory implications for large strings?
- Q: Can `str.replace()` be used with bytes objects?
- Q: What’s the difference between `replace()` and `str.translate()`?
- Q: How can I replace multiple substrings at once?
- Q: Does `str.replace()` support backreferences?
For example, replacing `"a"` with `"X"` in `"banana"` with `count=2` yields `"bXnana"`. The method’s deterministic nature ensures consistent results, but developers must account for edge cases, such as overlapping matches (e.g., `"aaa"` with `old="aa"` and `new="b"` would yield `"bab"` instead of `"bb"`). Understanding these mechanics is critical for debugging and optimizing `python string replace` operations in production environments.
Key Benefits and Crucial Impact
The `str.replace()` method’s primary advantage lies in its simplicity, reducing boilerplate code for common text transformations. Developers can replace substrings in a single line, making the codebase more maintainable and less prone to errors. This efficiency extends to performance, as the method avoids the overhead of regex compilation or external dependencies, making it ideal for high-frequency operations in loops or data pipelines.Beyond basic replacements, `python string replace` integrates seamlessly with other string methods, enabling powerful workflows. For instance, combining `replace()` with `split()` and `join()` allows for complex text parsing, such as removing specific markers from log files or normalizing user input. Its role in data cleaning—where inconsistencies must be standardized—further underscores its impact on real-world applications.
"The beauty of `str.replace()` is its balance: it solves 80% of text problems with 20% of the complexity."
—Guido van Rossum (Python Creator, in discussions on Python’s design philosophy)
Major Advantages
- Readability: The method’s syntax (`str.replace(old, new)`) is intuitive, requiring minimal explanation for new developers.
- Performance: For ASCII strings, it operates in O(n) time, making it efficient for large datasets.
- Flexibility: The optional `count` parameter allows granular control over replacements, from full-string transformations to targeted edits.
- Integration: Works seamlessly with other string methods (e.g., `split()`, `strip()`) for multi-step text processing.
- Memory Efficiency: Unlike regex-based solutions, it avoids creating intermediate objects, reducing memory overhead.

Comparative Analysis
While `str.replace()` excels in simplicity, other methods offer distinct advantages depending on the use case. Below is a comparison of key alternatives:| Method | Use Case |
|---|---|
| `str.replace()` | Simple substring replacement; no regex needed. Best for exact matches and performance-critical scenarios. |
| `re.sub()` (Regex) | Complex pattern matching (e.g., email validation, multi-character replacements). Overhead for simple cases. |
| `str.translate()` | Bulk character mappings (e.g., case conversion, Unicode normalization). Requires a translation table. |
| Manual Iteration | Custom logic (e.g., overlapping matches). More verbose and error-prone. |
Future Trends and Innovations
As Python continues to evolve, so too will its string-handling capabilities. Future iterations may introduce optimizations for Unicode-heavy operations or parallel processing for large-scale replacements. Additionally, the rise of machine learning in text processing could integrate `str.replace()`-like operations into higher-level libraries, abstracting away manual transformations in favor of automated cleaning pipelines.For now, developers should focus on mastering the current implementation while staying informed about emerging tools. The method’s enduring relevance suggests it will remain a staple, though its role may expand in tandem with Python’s broader ecosystem.

Conclusion
Python’s `str.replace()` method is more than a basic string operation—it’s a cornerstone of text manipulation in Python. Its simplicity belies its power, enabling developers to solve a wide range of problems with minimal code. By understanding its mechanics, edge cases, and integration with other tools, practitioners can leverage `python string replace` to build robust, efficient, and maintainable solutions.As text data grows in complexity, the method’s role will likely expand, particularly in domains like data science and automation. For developers, the key takeaway is to use `str.replace()` judiciously: recognize its strengths for exact matches and performance, but don’t hesitate to explore alternatives like regex or `translate()` when needed. Mastery of this tool is a stepping stone to deeper expertise in Python’s text-processing ecosystem.
Comprehensive FAQs
Q: Can `str.replace()` handle overlapping matches?
A: No. For example, replacing `"aa"` with `"b"` in `"aaa"` yields `"ba"` (not `"bb"`), as the method skips the second `"a"` after the first replacement. Use regex or manual iteration for overlapping cases.
Q: How does `str.replace()` perform with Unicode?
A: Unicode strings introduce variable-width characters, which can slow down the method. For large-scale Unicode processing, consider `str.translate()` or libraries like `unicodedata` for normalization.
Q: Is `str.replace()` case-sensitive?
A: Yes. To perform case-insensitive replacements, convert the string to lowercase/uppercase first (e.g., `text.lower().replace("old", "new")`) or use regex with the `re.IGNORECASE` flag.
Q: What happens if `old` is not found in the string?
A: The original string is returned unchanged. This behavior is consistent and avoids unnecessary operations.
Q: Can `str.replace()` modify strings in-place?
A: No. Strings in Python are immutable, so `replace()` always returns a new string. Assign the result to a variable to persist changes.
Q: How does `count` affect performance?
A: Specifying `count` can improve performance by limiting the number of scans, especially for large strings. However, the benefit diminishes if `count` is close to the total occurrences.
Q: Are there memory implications for large strings?
A: Yes. Each replacement creates a new string, which can consume significant memory for large inputs. For memory-intensive tasks, consider chunking or streaming approaches.
Q: Can `str.replace()` be used with bytes objects?
A: Yes, but the method behaves identically to strings. Use `bytes.replace()` for byte-level operations (e.g., in network protocols).
Q: What’s the difference between `replace()` and `str.translate()`?
A: `replace()` is for single-substring replacements, while `translate()` uses a mapping table for bulk character substitutions (e.g., converting all digits to `"X"`). `translate()` is faster for large-scale mappings.
Q: How can I replace multiple substrings at once?
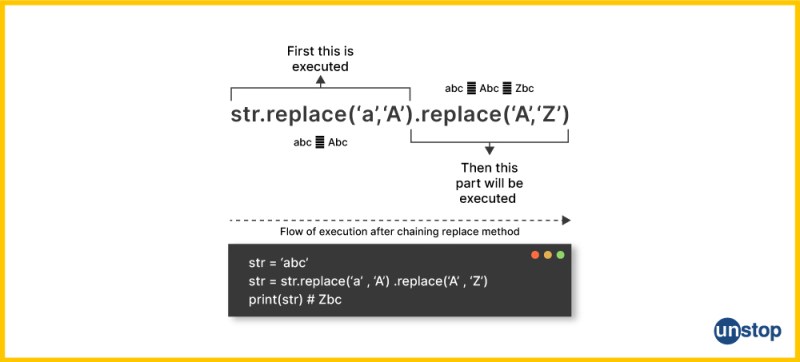
A: Chain multiple `replace()` calls or use `re.sub()` with a pattern like `re.compile("|".join(patterns))`. For example:
text.replace("a", "X").replace("b", "Y")
Q: Does `str.replace()` support backreferences?
A: No. Backreferences (e.g., `\1`) are a regex feature. For such cases, use `re.sub()` with capturing groups.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.