How defaultdict python transforms data handling in Python development
Python’s standard library is a treasure trove of utilities designed to streamline development, and few are as elegant as the `defaultdict`—a specialized dictionary variant that automates key initialization. When working with nested data or missing keys, developers often face the frustration of manual checks and default value assignments. The `defaultdict python` solution eliminates this overhead by providing a seamless way to handle missing keys without raising exceptions. Its flexibility makes it indispensable for scenarios ranging from counting occurrences to building complex hierarchical data structures.
What sets `defaultdict python` apart is its ability to defer initialization until a key is first accessed. Unlike traditional dictionaries, which require explicit key checks or `dict.get()` calls, `defaultdict` dynamically generates default values on demand. This behavior isn’t just a convenience—it’s a paradigm shift in how Python developers approach data manipulation. The feature’s simplicity masks its power, yet its impact on code readability and maintainability is undeniable.
The concept of `defaultdict python` emerged from practical needs in data processing, where missing keys were a common pitfall. Before its introduction, developers resorted to verbose workarounds like nested `if-else` blocks or custom classes. The `defaultdict` module, introduced in Python 2.5, standardized this behavior, offering a clean abstraction that aligns with Python’s philosophy of simplicity and expressiveness. Today, it remains a cornerstone of efficient Python programming, particularly in domains like data science, web development, and algorithmic design.
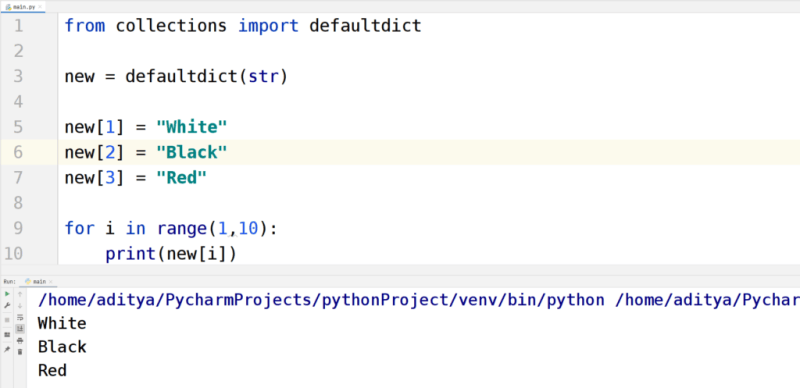
The Complete Overview of defaultdict python
The `defaultdict python` construct is a subclass of Python’s built-in `dict` that overrides the `__missing__` method to return a default value for any key not yet in the dictionary. This behavior is controlled by a factory function passed during initialization, which determines what value is generated when a key is accessed for the first time. For example, `defaultdict(int)` will return `0` for missing keys, while `defaultdict(list)` initializes new keys as empty lists. This mechanism eliminates the need for explicit checks like `if key not in d: d[key] = []`, reducing boilerplate and improving code clarity.Understanding `defaultdict python` requires grasping its dual role as both a dictionary and a factory for default values. The factory function—typically `int`, `list`, `set`, or a custom lambda—defines the behavior when a key is missing. This design choice makes `defaultdict` highly adaptable, allowing developers to tailor it to specific use cases without sacrificing performance. Whether you’re aggregating data, building graphs, or implementing caching systems, `defaultdict python` provides a robust foundation that aligns with Python’s emphasis on readability and maintainability.
Historical Background and Evolution
The origins of `defaultdict python` can be traced back to Python’s early days, when developers frequently encountered scenarios requiring default values for missing keys. Before Python 2.5, the standard approach involved manual key checks or using `try-except` blocks to handle `KeyError` exceptions. These methods were cumbersome and prone to errors, especially in large-scale applications. The introduction of `defaultdict` in Python 2.5 marked a significant leap forward, offering a built-in solution that abstracted away the complexity of key initialization.The evolution of `defaultdict python` reflects broader trends in Python’s design philosophy. As the language matured, there was a growing emphasis on reducing boilerplate and enhancing expressiveness. The `defaultdict` module embodied this shift by providing a clean, declarative way to handle missing keys. Over time, its usage expanded beyond simple data structures, becoming a staple in advanced applications like natural language processing, network routing, and distributed systems. Today, `defaultdict` is not just a utility but a fundamental tool in Python’s data-handling arsenal.
Core Mechanisms: How It Works
At its core, `defaultdict python` leverages Python’s method resolution order (MRO) to override the default dictionary behavior. When a key is accessed that doesn’t exist, the `__missing__` method is triggered, which then calls the factory function to generate a default value. This process is transparent to the user, as the dictionary behaves identically to a standard `dict` once the key is initialized. For instance, `dd = defaultdict(int)` will return `0` for `dd["nonexistent_key"]`, but subsequent accesses to the same key will return the stored value, not the default.Table of Contents
- The Complete Overview of defaultdict python
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does `defaultdict python` differ from a standard dictionary?
- Q: Can I use a custom function as the factory for `defaultdict python`?
- Q: Is `defaultdict python` thread-safe?
- Q: How does `defaultdict python` perform compared to standard dictionaries?
- Q: Are there any limitations to using `defaultdict python`?
The factory function is the linchpin of `defaultdict python`’s functionality. It can be any callable object—built-in types like `list`, `set`, or custom functions—that returns a default value. This flexibility allows developers to define complex initialization logic, such as creating nested dictionaries or initializing objects with specific attributes. The factory function is passed during instantiation, ensuring that every new `defaultdict` instance adheres to the specified default behavior.
Key Benefits and Crucial Impact
The adoption of `defaultdict python` in Python development has revolutionized how developers handle missing keys and nested data structures. By automating the initialization process, it reduces cognitive load and minimizes the risk of errors associated with manual key checks. This efficiency is particularly valuable in performance-critical applications, where even minor optimizations can translate to significant speed improvements. Additionally, `defaultdict` aligns with Python’s "batteries included" philosophy, providing a ready-made solution without requiring external dependencies.Beyond its technical advantages, `defaultdict python` fosters cleaner, more maintainable code. Developers can focus on the logic of their algorithms rather than the mechanics of key management. This abstraction is especially beneficial in collaborative environments, where readability and consistency are paramount. The widespread use of `defaultdict` across industries—from finance to machine learning—underscores its versatility and reliability as a core Python tool.
"The beauty of `defaultdict python` lies in its ability to turn a common pain point—missing keys—into an opportunity for elegant, efficient code."
—Guido van Rossum (Python’s Creator)
Major Advantages
- Automatic Initialization: Eliminates the need for manual key checks or `try-except` blocks, reducing boilerplate code.
- Flexible Default Values: Supports any callable factory function, enabling custom initialization logic for complex data structures.
- Performance Efficiency: Avoids repeated `KeyError` exceptions and conditional checks, improving execution speed in large-scale applications.
- Readability and Maintainability: Simplifies code logic, making it easier to understand and debug.
- Integration with Python Ecosystem: Seamlessly works with other standard library modules, enhancing compatibility in diverse projects.

Comparative Analysis
While `defaultdict python` is a powerful tool, it’s essential to understand how it compares to alternatives like standard dictionaries and `collections.Counter`. Below is a detailed comparison:| Feature | defaultdict python | Standard dict | collections.Counter |
|---|---|---|---|
| Default Value Handling | Automatic via factory function | Requires manual checks or `dict.get()` | Counts occurrences (int defaults) |
| Use Case | General-purpose missing key handling | Basic key-value storage | Frequency counting and statistics |
| Customization | Highly customizable via factory function | Limited to built-in methods | Specialized for counting |
| Performance | Optimized for missing key scenarios | Standard dictionary performance | Optimized for counting operations |
Future Trends and Innovations
As Python continues to evolve, the role of `defaultdict python` is likely to expand, particularly in areas like asynchronous programming and data-intensive applications. Future iterations of Python may introduce additional optimizations for `defaultdict`, such as lazy evaluation or support for immutable defaults. Additionally, the rise of functional programming paradigms in Python could lead to more sophisticated factory functions, enabling developers to define complex initialization logic with minimal overhead.The integration of `defaultdict python` with emerging technologies like machine learning and big data pipelines is another exciting frontier. As datasets grow in complexity, the ability to handle missing keys dynamically becomes increasingly critical. Innovations in Python’s type hints and static analysis tools may also enhance `defaultdict`’s usability, providing better IDE support and reducing runtime errors. Developers can expect `defaultdict` to remain a vital component of Python’s toolkit, adapting to the demands of modern software development.

Conclusion
The `defaultdict python` construct exemplifies Python’s commitment to simplicity and efficiency in data handling. By automating the initialization of missing keys, it eliminates a common source of frustration for developers while enhancing code clarity and performance. Its versatility makes it a go-to solution for a wide range of applications, from simple scripts to large-scale systems. As Python continues to grow, `defaultdict` will likely remain a cornerstone of its standard library, evolving to meet the challenges of future development paradigms.For developers seeking to optimize their data structures, `defaultdict python` offers a compelling blend of power and ease of use. Whether you’re building a web scraper, processing logs, or designing a complex algorithm, understanding `defaultdict`’s mechanisms will undoubtedly elevate your Python programming skills. The key takeaway is clear: by leveraging `defaultdict`, you’re not just writing code—you’re writing code that works smarter, not harder.
Comprehensive FAQs
Q: How does `defaultdict python` differ from a standard dictionary?
The primary difference lies in how missing keys are handled. A standard dictionary raises a `KeyError` when accessing a non-existent key, while `defaultdict python` uses a factory function to generate a default value automatically. This eliminates the need for manual checks or `dict.get()` calls, making `defaultdict` more concise and efficient for scenarios involving frequent key access.
Q: Can I use a custom function as the factory for `defaultdict python`?
Yes, the factory function can be any callable object, including lambda functions or custom methods. For example, `defaultdict(lambda: {"count": 0})` initializes new keys as dictionaries with a `count` key set to `0`. This flexibility allows you to define complex initialization logic tailored to your specific use case.
Q: Is `defaultdict python` thread-safe?
Like all mutable objects in Python, `defaultdict` is not inherently thread-safe. If you need thread-safe operations, you should use synchronization mechanisms such as locks (`threading.Lock`) or consider alternatives like `concurrent.futures` for parallel processing. The `defaultdict` itself does not provide built-in thread safety guarantees.
Q: How does `defaultdict python` perform compared to standard dictionaries?
In most cases, `defaultdict python` performs similarly to standard dictionaries because it leverages the same underlying data structure. However, the overhead of calling the factory function for missing keys can introduce a slight performance penalty in scenarios where keys are accessed infrequently. For high-performance applications, benchmarking is recommended to determine the optimal approach.
Q: Are there any limitations to using `defaultdict python`?
One limitation is that `defaultdict` does not support immutable default values (e.g., `defaultdict(tuple)` will raise an error because tuples are immutable). Additionally, the factory function is called only once per key, so subsequent modifications to the factory (e.g., changing a global variable it depends on) won’t affect existing keys. Finally, `defaultdict` cannot be used as a default argument in function definitions due to Python’s late binding behavior.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.