Debugging valueerror: setting an array element with a sequence in Python: A Deep Technical Breakdown
The "valueerror: setting an array element with a sequence" error is one of Python’s most cryptic yet common pitfalls for developers working with numerical arrays. Unlike syntax errors that halt execution immediately, this runtime exception often surfaces during data processing pipelines, where a seemingly valid assignment operation triggers a type conflict. The error’s ambiguity stems from Python’s dynamic typing system colliding with NumPy’s rigid array structure—where a scalar value might be replaced with a list, tuple, or another array without proper reshaping.
What makes this particular error insidious is its delayed manifestation. A developer might write code that compiles without warnings, only to encounter the exception during execution when iterating over datasets or performing element-wise operations. The root cause typically lies in attempting to assign a multi-dimensional sequence (like a list of lists) to a single array element, which NumPy interprets as an invalid operation unless explicitly reshaped or broadcasted.
Understanding this error requires dissecting three layers: the Python-NumPy interaction, the memory model of arrays, and the implicit type coercion rules. Unlike standard Python lists that can hold heterogeneous objects, NumPy arrays enforce homogeneous data types at initialization. When a developer assigns a sequence where the array expects a scalar, the interpreter raises `ValueError` to prevent silent data corruption—a safeguard that, while frustrating, is critical for numerical computing reliability.
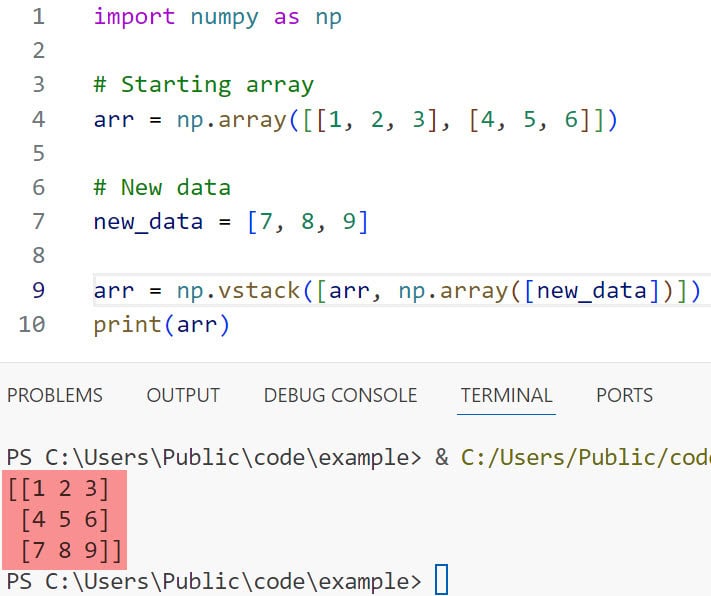
The Complete Overview of "valueerror: setting an array element with a sequence"
This error occurs exclusively in contexts where NumPy arrays (or similar typed arrays) attempt to store sequences in positions designed for scalar values. The confusion arises because Python’s built-in sequences (lists, tuples) are fundamentally different from NumPy’s ndarray objects. While a Python list can contain mixed types, a NumPy array requires all elements to conform to a single dtype (data type), such as `int32`, `float64`, or `bool`.The error message itself is deceptive in its simplicity. The phrase "setting an array element with a sequence" obscures the underlying issue: the assignment operation violates NumPy’s homogeneity constraint. For example, trying to assign `[1, 2]` to `array[0]` fails because the array expects a single integer, not a sub-array. The solution often involves reshaping the sequence to match the target array’s dimensionality or converting the sequence into a compatible scalar.
Debugging this error demands a methodical approach. Developers must first identify whether the sequence is being passed intentionally (e.g., during matrix operations) or accidentally (e.g., due to a loop misalignment). Tools like `np.array().shape` and `np.array().dtype` become indispensable for diagnosing dimensional mismatches, while `isinstance()` checks can reveal whether an object is a sequence before assignment.
Historical Background and Evolution
The `ValueError` in NumPy traces its lineage to Python’s core type system, which has evolved to handle dynamic typing while maintaining performance for numerical operations. NumPy, introduced in 2005 as a library for scientific computing, inherited Python’s flexibility but introduced strict typing to optimize memory access patterns. Early versions of NumPy (pre-1.0) were more forgiving with type coercion, allowing implicit conversions that modern versions reject to prevent subtle bugs.Table of Contents
- The Complete Overview of "valueerror: setting an array element with a sequence"
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does `arr[0] = [1, 2]` raise `ValueError` but `arr[0:2] = [1, 2]` work?
- Q: Can I suppress this error to make my code "work" temporarily?
- Q: How do I check if an object is a sequence before assignment?
- Q: What’s the difference between this error and `IndexError`?
- Q: Does this error occur in other libraries like TensorFlow or PyTorch?
- Q: How can I debug this error if the stack trace doesn’t point to the obvious line?
- Q: Are there performance implications to using `.item()` or `np.asscalar()`?
The error’s current form became standardized with NumPy 1.7 (2012), when the developers prioritized explicit behavior over implicit conversions. This shift was driven by two factors: (1) the rise of large-scale data processing where silent type errors could propagate undetected, and (2) the need for compatibility with C/Fortran libraries that expect strict dtype adherence. The trade-off was increased developer friction during debugging, but the long-term gain was robustness in production environments.
A lesser-known historical quirk is that this error was once more common in Pandas, where DataFrames (built on NumPy arrays) would raise similar exceptions when users attempted to assign Series objects to single-cell positions. Pandas mitigated this by introducing `.iat[]` for scalar access and `.loc[]` for label-based assignment, effectively segmenting the error’s occurrence.
Core Mechanisms: How It Works
At the lowest level, the error manifests when NumPy’s `__setitem__` method encounters an assignment where the right-hand side (RHS) is a sequence but the left-hand side (LHS) expects a scalar. The method first checks the target array’s `dtype` and `shape`. If the RHS is a sequence (detected via `collections.abc.Sequence`), NumPy evaluates whether it can be broadcasted to the target position. If not, it raises `ValueError`.The broadcasting rules are critical here. NumPy allows sequences to be assigned to array slices if their shapes are compatible (e.g., assigning `[1, 2]` to `array[0:2]` works if the array has at least 2 elements). However, assigning a sequence to a single element (`array[0] = [1, 2]`) fails because the target is a 0-dimensional scalar, and the RHS is 1-dimensional. The error message omits these details, forcing developers to infer the issue from context.
A hidden complexity involves NumPy’s handling of "scalar-like" sequences. For instance, `np.array([1])` is treated as a scalar in some contexts, but `list([1])` is not. This distinction explains why identical operations may succeed or fail based on whether the sequence is a NumPy array or a Python list.
Key Benefits and Crucial Impact
While the `ValueError` is often seen as a nuisance, it serves as a critical safeguard in numerical computing. By rejecting ambiguous assignments, NumPy prevents silent data corruption that could cascade through calculations, particularly in machine learning pipelines where input shapes must align precisely. The error’s specificity—occurring only during assignment—also helps isolate bugs to exact lines of code, unlike more generic exceptions that obscure their origin.The psychological impact on developers is equally significant. Encountering this error forces a pause in workflow, prompting a deeper examination of data structures. Over time, this habit reduces the likelihood of similar issues in other parts of the codebase, fostering a culture of defensive programming. Moreover, the error’s consistency across NumPy versions ensures that solutions documented today remain valid in future releases, unlike some Python built-in behaviors that change with interpreter updates.
"NumPy’s strict typing isn’t a limitation—it’s a feature. The `ValueError` you’re seeing isn’t a bug; it’s the system telling you that your data model doesn’t match the operation you’re trying to perform. Treat it as a design review, not a roadblock."
— Travis Oliphant, NumPy Core Developer (2015)
Major Advantages
- Data Integrity: Prevents accidental overwrites of array elements with incompatible sequences, which could corrupt numerical results in simulations or statistical analyses.
- Performance Optimization: By enforcing homogeneous dtypes, NumPy enables low-level optimizations (e.g., SIMD vectorization) that Python lists cannot leverage.
- Interoperability: Ensures compatibility with C/Fortran libraries and hardware accelerators (e.g., CUDA) that expect strictly typed arrays.
- Debugging Clarity: The error message, while terse, is unambiguous once the context is understood, unlike exceptions that require stack traces to diagnose.
- Future-Proofing: Adhering to NumPy’s rules prepares code for adoption in frameworks like TensorFlow or PyTorch, which inherit similar constraints.

Comparative Analysis
| Scenario | Behavior in NumPy |
|---|---|
| Assigning a list to a single array element (e.g., `arr[0] = [1, 2]`) | `ValueError: setting an array element with a sequence` (fails) |
| Assigning a list to a slice (e.g., `arr[0:2] = [1, 2]`) | Works if slice length matches list length (broadcasting) |
| Assigning a NumPy array to a single element (e.g., `arr[0] = np.array([1])`) | Works if the array is 0-dimensional (scalar-like) |
| Assigning a tuple to a single element (e.g., `arr[0] = (1, 2)`) | `ValueError` (tuples are sequences, even if immutable) |
Future Trends and Innovations
The handling of sequence assignments in NumPy is unlikely to change drastically, as the current behavior aligns with the library’s design philosophy. However, future versions may introduce optional "lenient mode" flags for educational purposes, allowing developers to test code paths without strict type enforcement. This would mirror Pandas’ `.copy()` behavior, where explicit copying is required to avoid `SettingWithCopyWarning`.Another emerging trend is the integration of static type checkers (e.g., `mypy` with NumPy type hints) that can catch potential `ValueError` scenarios at edit time. Tools like `numpy.typing` are already enabling this, allowing developers to annotate functions with expected array shapes and dtypes. As Python’s type system matures, these checks may reduce the frequency of runtime errors like this one.
For machine learning applications, frameworks are increasingly abstracting away NumPy’s low-level constraints. Libraries like JAX or PyTorch provide higher-level abstractions (e.g., tensors with automatic broadcasting) that handle sequence assignments more flexibly, though they still rely on NumPy’s underlying mechanisms for performance-critical operations.

Conclusion
The `ValueError: setting an array element with a sequence` is more than an error—it’s a reflection of NumPy’s commitment to performance and correctness in numerical computing. While it may initially frustrate developers accustomed to Python’s dynamic flexibility, mastering this error reveals deeper insights into array operations, broadcasting, and data type management. The key takeaway is to treat the error as a diagnostic tool rather than an obstacle, using it to validate assumptions about data shapes and types before assignment.As numerical computing evolves, the principles behind this error will remain relevant, even if the syntax changes. Understanding why NumPy rejects sequence assignments to scalar positions today prepares developers for similar constraints in tomorrow’s libraries, ensuring their code remains robust across paradigms.
Comprehensive FAQs
Q: Why does `arr[0] = [1, 2]` raise `ValueError` but `arr[0:2] = [1, 2]` work?
The first fails because `arr[0]` is a 0-dimensional scalar position, and NumPy cannot store a 1-dimensional sequence there. The second works because the slice `arr[0:2]` is a 1-dimensional target that matches the sequence’s length, enabling broadcasting.
Q: Can I suppress this error to make my code "work" temporarily?
While possible (e.g., using `try-except` blocks), this is discouraged. The error exists to prevent data corruption. Instead, reshape or convert the sequence to a scalar using `np.asscalar()` or `item()`.
Q: How do I check if an object is a sequence before assignment?
Use `isinstance(obj, collections.abc.Sequence)` to test for sequences. For NumPy-specific checks, combine this with `np.ndim(obj) > 0` to distinguish arrays from scalars.
Q: What’s the difference between this error and `IndexError`?
`IndexError` occurs when an index is out of bounds (e.g., `arr[100]` on a 10-element array). This `ValueError` occurs when the assigned value’s type/shape conflicts with the target position’s expectations.
Q: Does this error occur in other libraries like TensorFlow or PyTorch?
Yes, though the messages may vary. Both libraries build on NumPy’s array model and enforce similar constraints. For example, PyTorch raises `RuntimeError: expected scalar type` for analogous cases.
Q: How can I debug this error if the stack trace doesn’t point to the obvious line?
Use `np.debug()` or `np.seterr(all='raise')` to enable detailed error messages. Also, inspect intermediate variables with `print(arr.shape, type(value))` to identify shape/dtype mismatches.
Q: Are there performance implications to using `.item()` or `np.asscalar()`?
Minimal for small arrays, but these methods copy data to Python scalars, which can introduce overhead in tight loops. For large datasets, pre-validate shapes/dtypes to avoid runtime conversions.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.