How Queue Java Reshapes Modern Software Architecture
The term queue Java doesn’t just refer to a data structure—it’s a paradigm shift in how modern applications handle asynchronous workloads. At its core, Java’s queue implementations (from `BlockingQueue` to Kafka integrations) are the silent architects of scalability, enabling systems to process millions of operations without collapsing under load. Unlike traditional synchronous calls, a well-optimized queue Java setup decouples producers from consumers, allowing developers to build resilient pipelines where failures in one component don’t halt the entire workflow. This isn’t just theory; it’s the reason why financial trading platforms, real-time analytics engines, and e-commerce backends rely on Java’s queue mechanisms to stay operational during peak traffic.
Yet, the power of queue Java extends beyond raw performance. It’s a design philosophy that enforces modularity—each queue acts as a bounded context, isolating business logic into discrete, testable units. When a microservice needs to offload a task (like processing a payment or generating a report), it doesn’t block the main thread; instead, it hands the job to a queue, where workers pull tasks at their own pace. This separation of concerns isn’t just elegant—it’s a necessity in distributed systems where latency and consistency are non-negotiable. The result? Applications that scale horizontally without sacrificing reliability.
But here’s the catch: not all queue Java implementations are created equal. A poorly configured `LinkedBlockingQueue` can become a bottleneck, while a misaligned Kafka topic partition strategy might introduce unnecessary latency. The devil lies in the details—thread pools, backpressure algorithms, and even JVM garbage collection behavior all interact with queue performance in ways that aren’t immediately obvious. Mastering queue Java requires understanding these nuances, from the low-level mechanics of `wait()`/`notify()` to the high-level trade-offs of eventual consistency in distributed messaging.

The Complete Overview of Queue Java
Java’s queue ecosystem is a layered architecture, where each component serves a distinct purpose. At the foundational level, the Java Collections Framework provides thread-safe queues like `ArrayBlockingQueue` and `PriorityBlockingQueue`, designed for in-memory concurrency. These are the building blocks for single-JVM applications, where producers and consumers operate within the same process. However, when systems grow beyond a single machine, Java’s queue capabilities expand to include distributed messaging systems like Apache Kafka, RabbitMQ, and ActiveMQ. These tools bridge the gap between local and remote communication, enabling true decoupling of services across clusters.
The choice between these layers isn’t arbitrary—it’s dictated by the application’s requirements. A high-frequency trading system might prioritize nanosecond-level latency with an in-memory `ConcurrentLinkedQueue`, while a log-processing pipeline could leverage Kafka’s durability and partition tolerance. The key is alignment: the queue’s characteristics (FIFO vs. priority, bounded vs. unbounded) must match the workload’s demands. For example, a bounded queue with a fixed capacity enforces backpressure, preventing producers from overwhelming consumers, whereas an unbounded queue risks memory exhaustion if not monitored. This balance between flexibility and control is what makes queue Java both a tool and a discipline.
Historical Background and Evolution
The origins of queue Java trace back to the early 2000s, when Java’s concurrency utilities were still in their infancy. Before `java.util.concurrent`, developers relied on synchronized blocks and manual `wait()`/`notify()` calls—a fragile approach prone to deadlocks and starvation. The introduction of `BlockingQueue` in Java 5 (2004) marked a turning point, offering a high-level abstraction for thread-safe queues with built-in blocking semantics. This innovation didn’t just simplify code; it enabled scalable architectures by abstracting away the complexities of low-level synchronization.
Table of Contents
- The Complete Overview of Queue Java
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between a BlockingQueue and a non-blocking queue in Java?
- Q: How does Kafka’s queue model differ from Java’s BlockingQueue?
- Q: Can I use a Java queue for real-time processing (e.g., stock trading)?h3> A: Yes, but with caveats. For nanosecond-level latency, use `ConcurrentLinkedQueue` or `LinkedBlockingQueue` with direct `put()`/`take()` calls. Avoid distributed queues (like Kafka) unless you need persistence or cross-machine communication. Also, ensure your thread pool and JVM settings (e.g., `-Xms`, `-Xmx`) are optimized for low-latency scenarios. Q: What’s the best way to handle backpressure in a Java queue?
- Q: How do I monitor and tune a Java queue for performance?
As distributed systems gained traction, Java’s queue ecosystem evolved to include libraries like Apache Camel and Spring Integration, which provided declarative ways to wire queues into larger workflows. Meanwhile, the rise of big data and real-time analytics pushed Java’s queue implementations into new territory. Kafka, with its log-based architecture, became the de facto standard for event streaming, while libraries like Reactor (for reactive programming) integrated queues into non-blocking I/O models. Today, queue Java isn’t just about concurrency—it’s about orchestrating entire data flows, from ingestion to processing to storage, with minimal coupling between components.
Core Mechanisms: How It Works
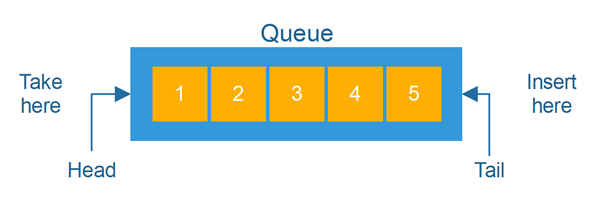
At its simplest, a queue Java operates on the FIFO (First-In-First-Out) principle, but the mechanics vary depending on the implementation. In-memory queues like `LinkedBlockingQueue` use a linked list to store elements, with `put()` and `take()` operations synchronized to prevent race conditions. Under the hood, these methods rely on `ReentrantLock` and `Condition` variables to signal between threads, ensuring that producers block when the queue is full and consumers block when it’s empty. The elegance lies in the atomicity: no two threads can corrupt the queue’s state simultaneously.
Distributed queues introduce additional layers of complexity. Kafka, for instance, treats each topic as a partitioned log, where producers append records to partitions and consumers read from offsets. Java clients like `kafka-clients` abstract this complexity, but the underlying mechanics—such as leader election for partition replicas or the `fetch.min.bytes` configuration—directly impact throughput. Similarly, RabbitMQ’s AMQP model uses exchanges and bindings to route messages, while Java’s `RabbitTemplate` handles serialization and acknowledgment logic. The common thread? All these systems enforce isolation between producers and consumers, allowing independent scaling of each component.
Key Benefits and Crucial Impact
The adoption of queue Java isn’t just about solving technical challenges—it’s about redefining how applications interact with each other. By decoupling producers from consumers, queues eliminate tight coupling, making systems more resilient to failures. If a consumer crashes, the queue buffers the messages until recovery; if a producer fails, the queue ensures no data is lost. This reliability is critical in industries like healthcare (where patient records must be processed accurately) or finance (where transactions can’t be retried indefinitely). The result is a shift from fragile, monolithic systems to elastic, fault-tolerant architectures.
Beyond reliability, queue Java enables horizontal scaling like never before. In a traditional request-response model, adding more load requires scaling the entire server. With queues, you can scale consumers independently—adding more workers to process messages without touching the producers. This decoupling also simplifies testing: queues allow you to mock external dependencies, isolate components, and even replay past messages for debugging. The impact isn’t just operational; it’s architectural, pushing Java applications toward modularity and maintainability.
"A queue isn’t just a data structure—it’s a contract between producers and consumers, defining how they interact without knowing each other’s details."
— Martin Fowler, Patterns of Enterprise Application Architecture
Major Advantages
- Decoupling: Producers and consumers operate independently, reducing interdependencies and improving fault isolation.
- Scalability: Horizontal scaling of consumers is straightforward, as queues act as buffers to absorb variable loads.
- Backpressure Handling: Bounded queues enforce limits, preventing system overload from unchecked message production.
- Order Preservation: FIFO queues guarantee message sequencing, critical for workflows like order processing or audit logs.
- Integration Flexibility: Java queues can interface with databases, APIs, or other queues, serving as a universal adapter layer.

Comparative Analysis
| In-Memory Queues (e.g., BlockingQueue) | Distributed Queues (e.g., Kafka, RabbitMQ) |
|---|---|
| Low latency (<1ms for local operations) | Higher latency (network overhead, 10–100ms) |
| Limited to single-JVM scope | Cross-machine communication, cluster-wide |
| No persistence by default (volatile) | Durable storage (Kafka retains logs for days/weeks) |
| Best for thread-bound workloads (e.g., task scheduling) | Ideal for event-driven architectures (e.g., real-time analytics) |
Future Trends and Innovations
The next evolution of queue Java will likely focus on two fronts: performance optimization and integration with emerging paradigms. As Java’s Project Loom introduces virtual threads, queues will need to adapt to lightweight concurrency models, where thousands of threads can coexist without the overhead of OS threads. Meanwhile, the rise of serverless computing will push queue implementations to support event-driven serverless functions, where messages trigger ephemeral workers. Tools like Quarkus and Micronaut are already exploring how to streamline queue-based serverless workflows, reducing cold-start latency.
On the data side, queues will become more intelligent, incorporating machine learning for dynamic load balancing or anomaly detection in message flows. Imagine a queue that auto-scales partitions based on real-time traffic patterns or a Kafka consumer that prioritizes messages using reinforcement learning. These innovations will blur the line between messaging systems and data pipelines, turning queues into active participants in the application logic rather than passive intermediaries. The goal? To make queue Java not just a feature, but the nervous system of next-generation software.
Conclusion
Queue Java is more than a technical detail—it’s the backbone of modern, resilient systems. Whether you’re optimizing a monolith’s internal communication or designing a distributed microservice ecosystem, the principles remain the same: decouple, scale, and isolate. The tools have evolved from simple `BlockingQueue` implementations to Kafka clusters and reactive streams, but the core idea persists: queues are the invisible threads that keep complex systems running smoothly. Ignore them at your peril; master them, and you gain the power to build applications that are not just fast, but fault-tolerant, scalable, and future-proof.
The challenge now is to move beyond treating queues as afterthoughts and instead design them into the architecture from the start. That means choosing the right queue for the job—whether it’s an in-memory `ConcurrentLinkedQueue` for ultra-low-latency needs or a Kafka topic for global event distribution—and tuning it for performance, reliability, and cost. The systems that thrive in the coming years won’t be those with the most lines of code, but those with the most thoughtful queue designs.
Comprehensive FAQs
Q: What’s the difference between a BlockingQueue and a non-blocking queue in Java?
A: A `BlockingQueue` (e.g., `ArrayBlockingQueue`) automatically blocks producers when full and consumers when empty, using internal locks. Non-blocking alternatives like `ConcurrentLinkedQueue` rely on atomic operations (e.g., `CAS`) to avoid blocking, but they don’t guarantee FIFO order or blocking behavior. Choose blocking queues for simplicity and non-blocking for ultra-low-latency, lock-free scenarios.
Q: How does Kafka’s queue model differ from Java’s BlockingQueue?
A: Kafka treats topics as partitioned logs, where messages are append-only and consumers read from offsets. Java’s `BlockingQueue` is in-memory, unpersisted, and operates within a single JVM. Kafka’s model is durable, distributed, and optimized for high-throughput event streaming, while `BlockingQueue` is lightweight and ideal for thread-bound tasks.
Q: Can I use a Java queue for real-time processing (e.g., stock trading)?h3>
A: Yes, but with caveats. For nanosecond-level latency, use `ConcurrentLinkedQueue` or `LinkedBlockingQueue` with direct `put()`/`take()` calls. Avoid distributed queues (like Kafka) unless you need persistence or cross-machine communication. Also, ensure your thread pool and JVM settings (e.g., `-Xms`, `-Xmx`) are optimized for low-latency scenarios.
Q: What’s the best way to handle backpressure in a Java queue?
A: Use a bounded `BlockingQueue` with a fixed capacity and configure producers to reject or retry messages when the queue is full. For distributed systems, implement circuit breakers or dynamic scaling of consumers. Libraries like Spring Retry or Resilience4j can automate retry logic, while Kafka’s `max.block.ms` helps manage producer/consumer stalls.
Q: How do I monitor and tune a Java queue for performance?
A: Key metrics include queue size, producer/consumer latency, and thread pool utilization. Use tools like Micrometer (with Prometheus) to track these, and tune parameters like:
- `BlockingQueue` capacity (avoid overloading consumers)
- Thread pool size (too many threads increase context-switching overhead)
- Batch sizes (for bulk operations in distributed queues)
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.