The Definitive Guide to Splitting Names in Excel: How to Separate First and Last Name in Excel
Every dataset containing full names—whether from CRM systems, HR records, or customer databases—requires structured separation. The ability to split first and last names in Excel isn’t just a technical task;
it’s the foundation for accurate sorting, filtering, and analysis. Without this separation, even the most sophisticated reports risk misclassification, skewed metrics, or compliance violations. The stakes are higher in regulated industries where names must align with legal standards, yet the solution remains surprisingly accessible.
Most professionals overlook the subtleties of name parsing. A simple comma might distinguish "Smith, John" from "John Smith," while prefixes ("Dr. Michael") or suffixes ("Maria Rodriguez Jr.") introduce layers of complexity. Excel’s native tools—often dismissed as rudimentary—can handle these variations with precision, provided you understand their limits and workarounds. The key lies in recognizing when to use formulas, when to leverage Power Query, and how to preprocess data to avoid common pitfalls.
This guide demystifies the process, covering everything from basic text functions to advanced automation. Whether you’re dealing with a single column of names or a dataset spanning thousands of entries, the methods here ensure clean, reproducible results. The focus isn’t just on how to separate first and last name in Excel but on doing it efficiently, scalably, and without manual errors.
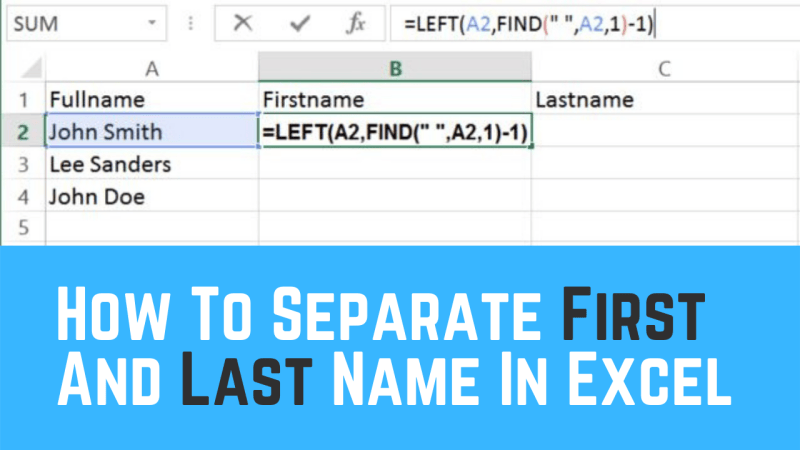
The Complete Overview of Splitting Names in Excel
Excel’s text-splitting capabilities are deceptively powerful. At its core, the task hinges on identifying delimiters—commas, spaces, or custom separators—and extracting substrings based on position. However, real-world data rarely adheres to a single pattern. Names may include middle names, hyphenated surnames, or non-standard formatting (e.g., "Van der Waals, Albert"). The solution requires a layered approach: first identifying the dominant pattern, then applying conditional logic to handle exceptions.
For most users, the journey begins with LEFT, RIGHT, or MID functions, which extract text based on character count. These work for predictable formats but fail when names vary in length. More robust methods—like TEXTSPLIT (Excel 365) or TEXTBEFORE/TEXTAFTER—offer flexibility by targeting specific delimiters. The choice of method depends on your Excel version, data volume, and tolerance for manual intervention.
Historical Background and Evolution
The evolution of name-splitting in Excel mirrors broader trends in data processing. Early versions (pre-2007) relied on cumbersome array formulas or VBA macros to parse text, a process that demanded programming knowledge. The introduction of TEXTSPLIT in Excel 365 marked a paradigm shift, democratizing advanced text manipulation for non-coders. Similarly, Power Query—originally a Power BI feature—was integrated into Excel 2016, offering a graphical interface for complex transformations, including name extraction.
Table of Contents
- The Complete Overview of Splitting Names in Excel
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I split names where the format alternates between "First Last" and "Last, First"?
- Q: Can I split names with middle names or initials (e.g., "John A. Smith")?
- Q: Why does my FIND -based formula fail for names like "O'Connor" or "Van der Waals"?
- Q: How can I split names in Power Query without errors?
- Q: What’s the fastest way to split 10,000+ names in Excel?
- Q: How do I handle names with prefixes/suffixes (e.g., "Dr. Jane Doe Jr.")?
- Q: Can I split names in Google Sheets using similar methods?
Understanding this history is crucial because older methods (e.g., FIND + MID combinations) persist in legacy workflows. While functional, they lack the scalability of modern tools. For instance, a FIND-based solution might break when a name contains multiple spaces or non-alphabetic characters. By contrast, TEXTSPLIT handles these cases natively, reducing the need for error-prone workarounds.
Core Mechanisms: How It Works
The mechanics of splitting names revolve around two principles: ;
and positional extraction. Delimiters act as anchors—commas in "Last, First" formats, spaces in "First Last" structures, or even semicolons in imported datasets. Excel’s text functions then isolate segments based on these anchors. For example, TEXTBEFORE(A1, ", ") extracts everything before a comma-space, while TEXTAFTER(A1, " ") captures the last word in a space-delimited string.
Positional extraction, however, is more nuanced. Functions like LEFT and RIGHT require knowing the exact length of the first or last name, which is impractical for variable-length data. Instead, MID combined with FIND dynamically locates delimiters. For instance, MID(A1, FIND(" ", A1)+1, LEN(A1)) extracts the last name by finding the first space and returning all subsequent characters. This approach fails only when names lack spaces (e.g., single-word surnames), necessitating fallback logic.
Key Benefits and Crucial Impact
Accurate name separation isn’t just about tidying data—it’s about enabling downstream functionality. Structured names improve sorting, merging datasets, and generating personalized communications. In sales CRM systems, for example, separating "Doe, John" into first and last names allows for proper address labeling ("Dear John Doe") and compliance with GDPR’s "clear and transparent" data-handling requirements. Similarly, HR departments use split names to validate employee records against government databases.
The impact extends to automation. Once names are separated, they can trigger conditional formatting, populate dropdowns, or feed into dynamic reports. Without this step, even the most sophisticated Excel models risk inaccuracies. The cost of manual splitting—hours spent on repetitive tasks—pales in comparison to the efficiency gains from automated workflows.
"Data cleaning is often the most underestimated step in analytics. A single misplaced comma in a name can cascade into errors across an entire report."
— Karen Lopez, Data Management Expert
Major Advantages
- Precision in Variable Data: Methods like
TEXTSPLITadapt to irregular formats (e.g., "Jean-Luc Picard" vs. "Picard, Jean-Luc"), reducing manual overrides. - Scalability: Power Query can process millions of rows without performance degradation, unlike iterative formulas.
- Compliance Readiness: Structured names simplify audits by ensuring consistency with regulatory standards (e.g., HIPAA for patient records).
- Integration with Other Tools: Split names can be exported to Power BI, Python (via
pandas), or SQL databases for further analysis. - Future-Proofing: Modern functions (e.g.,
TEXTBEFORE) reduce reliance on fragileFIND-based solutions.

Comparative Analysis
| Method | Best Use Case |
|---|---|
TEXTSPLIT (Excel 365) |
Large datasets with consistent delimiters (e.g., "First Last" or "Last, First"). Handles multiple columns and custom separators. |
Power Query |
Complex datasets with mixed formats (e.g., "Dr. Smith-Johnson" or "O'Connor, Mary"). Supports step-by-step transformations. |
LEFT/RIGHT + FIND |
Legacy Excel versions or simple, uniform data (e.g., "Last, First" with no exceptions). Requires manual adjustments for edge cases. |
| VBA Macro | Highly customized splitting logic (e.g., parsing "Sir William Shakespeare" into title, first, last). Overkill for basic needs. |
Future Trends and Innovations
The next frontier in name separation lies in AI-driven automation. Tools like Excel’s Ideas feature (2023+) can now suggest splitting logic based on sample data, reducing the need for manual function selection. Meanwhile, machine learning models trained on global name patterns (e.g., distinguishing "Lee" as a surname in Korean vs. English contexts) are being integrated into enterprise data platforms. For now, Excel users can leverage TEXTBEFORE/TEXTAFTER with custom delimiters to mimic these capabilities, but the trend is clear: future-proof solutions will combine rule-based logic with adaptive learning.
Another emerging trend is the integration of name-splitting with entity recognition APIs (e.g., Azure Cognitive Services). These services can identify titles ("Prof. Dr."), honorifics ("Ms."), and even transliterate names across languages. While overkill for most Excel users, they highlight the direction: from static formulas to dynamic, context-aware parsing. For today’s practitioners, mastering how to separate first and last name in Excel remains essential, but the horizon suggests even smarter tools ahead.

Conclusion
Separating first and last names in Excel is a gateway skill for data professionals. The methods outlined here—from TEXTSPLIT to Power Query—offer scalable solutions for any dataset, provided you account for variability. The key takeaway is adaptability: no single function works universally, but combining techniques (e.g., TEXTBEFORE for primary splits + FILTERXML for complex cases) ensures robustness. For teams, this means cleaner reports; for individuals, it means saving hours of manual work.
As Excel evolves, so too will the tools for name parsing. Today’s best practice—using TEXTSPLIT or Power Query—may be tomorrow’s baseline. The principles, however, remain timeless: understand your data’s quirks, choose the right tool for the job, and automate relentlessly. Whether you’re splitting names for a client list or preparing data for a global CRM, the goal is the same: precision without compromise.
Comprehensive FAQs
Q: How do I split names where the format alternates between "First Last" and "Last, First"?
A: Use a combination of IF and TEXTBEFORE/TEXTAFTER. For example:
=IF(FIND(",", A1)>0, TEXTBEFORE(A1, ", ") & " " & TEXTAFTER(A1, ", "), TEXTBEFORE(A1, " "))
This checks for a comma first, then falls back to space-based splitting.
Q: Can I split names with middle names or initials (e.g., "John A. Smith")?
A: Yes. Use TEXTSPLIT with custom delimiters:
=TEXTSPLIT(A1, " ", , TRUE)
This splits on spaces and returns an array, where the first and last elements are the first/last names. For "John A. Smith," the result would be {"John", "A.", "Smith"}.
Q: Why does my FIND-based formula fail for names like "O'Connor" or "Van der Waals"?
A: Hyphenated or multi-word surnames break space-based delimiters. Instead, use TEXTBEFORE with a comma or a custom separator:
=TEXTBEFORE(A1, " ") (for "First Last") or =TEXTBEFORE(A1, ", ") (for "Last, First"). For hyphens, combine with SUBSTITUTE:
=TEXTBEFORE(SUBSTITUTE(A1, "-", " "), " ").
Q: How can I split names in Power Query without errors?
A: In Power Query:
1. Select the name column.
2. Go to Add Column > Extract > Text Before Delimiter (choose comma or space).
3. For "First Last," use Text After Delimiter with space, then merge columns.
4. Handle errors by replacing blanks with null or default values in the Replace Values step.
Q: What’s the fastest way to split 10,000+ names in Excel?
A: Use TEXTSPLIT in Excel 365 for speed, or Power Query for scalability:
1. Load data into Power Query (Data > Get Data > From Table/Range).
2. Add a custom column with Text.BeforeDelimiter([Name], " ") for first names.
3. Repeat for last names, then load back to Excel.
Power Query processes this in seconds, regardless of row count.
Q: How do I handle names with prefixes/suffixes (e.g., "Dr. Jane Doe Jr.")?
A: Use nested TEXTBEFORE functions:
=TEXTBEFORE(TEXTAFTER(A1, " "), " ") extracts "Jane" from "Dr. Jane Doe Jr."
For suffixes, combine with TRIM and SUBSTITUTE:
=TRIM(SUBSTITUTE(TEXTBEFORE(A1, " Jr."), " Jr.", "")).
Q: Can I split names in Google Sheets using similar methods?
A: Yes, but with limitations. Google Sheets lacks TEXTSPLIT, so use:
=SPLIT(A1, " ") for space-delimited names, then reference array positions (e.g., =INDEX(SPLIT(A1, " "), 1, 1) for first name).
For "Last, First," use =REGEXEXTRACT(A1, "(.+),\s(.+)") with custom parsing.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.