Mastering Conda Create Environment: A Deep Technical Guide
The `conda create environment` command is the cornerstone of reproducible data science workflows, offering a structured way to isolate dependencies without conflicts. Unlike traditional Python virtual environments, which rely solely on `pip`, conda environments manage both Python packages and non-Python libraries—critical for scientific computing stacks. The ability to freeze exact versions of packages, from NumPy to CUDA drivers, ensures experiments run identically across teams or machines. Yet, many users overlook its full potential, treating it as a mere alternative to `venv` without exploring its deeper capabilities.
Behind the scenes, `conda create environment` leverages Anaconda’s package repository, a curated collection of over 15,000 pre-built binaries. This eliminates the "works on my machine" problem by providing deterministic builds. The command’s flexibility extends beyond Python: it can install system-level dependencies (e.g., `libgcc`, `zlib`) alongside Python packages, making it indispensable for ML pipelines requiring GPU acceleration or legacy libraries. However, this power comes with trade-offs—understanding them is key to avoiding common pitfalls like dependency resolution failures or bloated environment sizes.
What distinguishes `conda create environment` from other tools is its integration with channel priorities, environment variables, and even Docker integration. A poorly configured environment can derail a project, but mastering its syntax—from specifying exact package versions to excluding conflicts—transforms it into a precision instrument. Below, we dissect its mechanics, advantages, and how it stacks up against alternatives, ensuring you wield it effectively in production-grade workflows.

The Complete Overview of Conda Create Environment
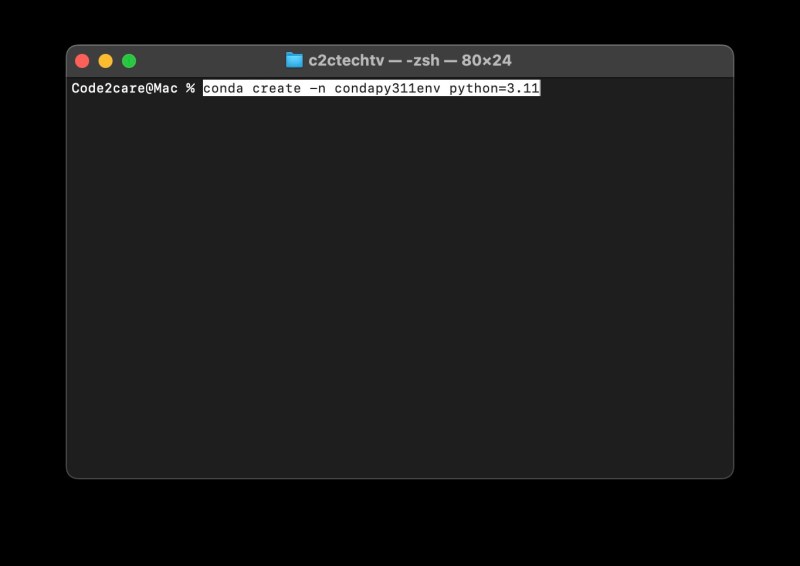
At its core, `conda create environment` is a command-line instruction that initializes a self-contained namespace for software dependencies. This namespace, or "environment," encapsulates all installed packages, their versions, and system libraries, ensuring isolation from the base conda installation or other environments. The command’s syntax is deceptively simple: `conda create --name myenv python=3.9 numpy pandas`, yet its implications are profound. For instance, specifying `python=3.9` pins the Python interpreter version, while omitting it defaults to conda’s latest stable release—a critical distinction when migrating code between systems.The command’s output—visible during creation—reveals the dependency resolution process, where conda’s solver attempts to satisfy all constraints. This transparency is invaluable for debugging: if the solver fails, the error message often points to incompatible package versions or missing channels. Advanced users can further customize environments with `conda config` or by editing the `environment.yml` manifest, which serializes the environment’s state for sharing. This level of control is rare in package managers, making conda a unique tool for both development and deployment.
Historical Background and Evolution
Conda’s origins trace back to 2012, when Anaconda Inc. sought a solution to the "dependency hell" plaguing scientific Python users. Traditional virtual environments (via `virtualenv`) struggled with non-Python libraries, forcing researchers to manually install system packages—a tedious and error-prone process. Conda addressed this by adopting a graph-based dependency resolver, inspired by tools like `apt` and `yum`, but tailored for cross-platform compatibility. The `conda create environment` command emerged as the primary interface for this system, offering a declarative way to define environments without manual intervention.Over time, conda evolved to support multi-user installations, Docker integration, and even GPU-accelerated packages. The introduction of `mamba`, a drop-in replacement for conda’s solver, further improved performance by using the `libsolv` algorithm, reducing resolution time from minutes to seconds for complex environments. These innovations underscore conda’s adaptability, yet its core philosophy—reproducibility through environment encapsulation—remains unchanged. Today, `conda create environment` is not just a tool but a standard practice in data science, bioinformatics, and engineering teams where dependency management is non-negotiable.
Core Mechanisms: How It Works
Under the hood, `conda create environment` triggers a multi-stage process. First, conda consults its package index (stored in the `pkgs` directory) to locate compatible versions of requested packages. This index is built from channels—remote repositories like `conda-forge` or `defaults`—and local caches. The solver then constructs a dependency graph, ensuring no conflicts exist between packages (e.g., a package requiring Python 3.8 cannot coexist with one requiring 3.10). If successful, conda downloads binaries and installs them to the environment’s directory (typically `~/anaconda3/envs/myenv`).Table of Contents
- The Complete Overview of Conda Create Environment
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can I use `conda create environment` with Python packages not available in conda?
- Q: How do I share a conda environment with a teammate?
- Q: Why does `conda create environment` sometimes fail to resolve dependencies?
- Q: Is there a performance difference between `conda create environment` and `mamba create`?
- Q: Can I delete a conda environment without affecting my base installation?
- Q: How do I list all existing conda environments?
- Q: What’s the best practice for naming conda environments?
- Q: Can I use `conda create environment` on Windows Subsystem for Linux (WSL)?
- Q: How do I update all packages in a conda environment?
- Q: Why does my conda environment take up more disk space than expected?
What sets conda apart is its handling of non-Python dependencies. For example, installing `tensorflow` via `conda create environment` automatically pulls in `libcuda` and other system libraries, whereas `pip` would leave these unresolved. This integration is managed through conda’s "build string" system, where packages include metadata about their dependencies, including platform-specific requirements. The result is an environment that is both self-contained and portable, provided the underlying OS architecture matches.
Key Benefits and Crucial Impact
The adoption of `conda create environment` has revolutionized how teams manage software stacks, particularly in fields where compatibility is paramount. Data scientists no longer waste hours debugging environment mismatches; instead, they can replicate entire workflows with a single command. This efficiency extends to collaboration: sharing an `environment.yml` file ensures every team member—regardless of their local setup—can reproduce the exact development or production environment. The impact is measurable in reduced onboarding time and fewer "it works on my machine" incidents.Beyond technical advantages, conda environments foster consistency across diverse hardware. A researcher using a high-performance cluster can share an environment with a colleague on a laptop, confident that the only variable is computational power, not missing dependencies. This uniformity is especially critical in machine learning, where model training often requires specific CUDA versions or BLAS implementations. The ability to encapsulate these dependencies in a single command transforms `conda create environment` from a utility into a strategic asset.
"Conda environments are the difference between a project that scales and one that collapses under its own weight." — Dr. Elena Vasileva, Senior Data Scientist at MIT
Major Advantages
- Dependency Isolation: Encapsulates all packages (Python and non-Python) in a single namespace, preventing conflicts with the base environment or other projects.
- Reproducibility: Environments can be serialized to `environment.yml` and shared, ensuring identical setups across teams or deployments.
- Performance Optimization: Pre-built binaries from channels like `conda-forge` reduce build times compared to compiling from source.
- System-Level Control: Unlike `pip`, conda can install OS libraries (e.g., `libgcc`, `zlib`), making it suitable for full-stack applications.
- Integration with Tools: Works seamlessly with Jupyter notebooks, Docker, and CI/CD pipelines (e.g., GitHub Actions), streamlining workflows.
Comparative Analysis
| Feature | Conda Create Environment | Python Virtualenv | Poetry/Pipenv |
|---|---|---|---|
| Non-Python Dependencies | ✅ Supports system libraries (e.g., CUDA, BLAS) | ❌ Limited to Python packages | ❌ Limited to Python packages |
| Dependency Resolution | ✅ Graph-based solver with channel priorities | ❌ Basic resolution (first-match wins) | ✅ Advanced but Python-only |
| Environment Sharing | ✅ `environment.yml` for full reproducibility | ❌ Requires `requirements.txt` (no system deps) | ✅ `pyproject.toml` but limited to Python |
| Performance | ✅ Pre-built binaries (faster installs) | ❌ Compilation required for some packages | ✅ Fast but limited to pip |
Future Trends and Innovations
The future of `conda create environment` lies in tighter integration with cloud-native tools and AI-driven dependency management. Projects like `micromamba` (a lightweight conda alternative) are reducing environment creation time to near-instantaneous levels, making it feasible to spin up disposable environments for CI/CD pipelines. Additionally, conda’s solver is being enhanced with machine learning to predict optimal package combinations, further reducing resolution failures. For data scientists, this means environments that adapt dynamically to new package releases without manual intervention.Another emerging trend is the convergence of conda with containerization. Tools like `conda-pack` already allow exporting environments to Docker images, but future iterations may embed conda’s solver directly into container orchestration platforms. This would eliminate the need for users to manually specify base images, instead generating them on-the-fly from `environment.yml` files. As AI-driven development tools gain traction, `conda create environment` could also incorporate automated dependency updates, ensuring environments stay current without breaking existing workflows.

Conclusion
`Conda create environment` is more than a command—it’s a paradigm shift in how developers and researchers manage dependencies. Its ability to handle both Python and system-level packages, combined with robust reproducibility features, makes it indispensable in fields where precision matters. While alternatives like `pip` or `virtualenv` suffice for simple projects, conda’s depth is unmatched for complex stacks. The key to leveraging it effectively lies in understanding its mechanics: from channel priorities to solver behavior—and knowing when to use it versus lighter tools like `poetry`.As the ecosystem evolves, staying updated on innovations like `micromamba` or AI-assisted dependency resolution will ensure environments remain efficient and future-proof. For now, `conda create environment` remains the gold standard for those who demand reliability in their software stacks.
Comprehensive FAQs
Q: Can I use `conda create environment` with Python packages not available in conda?
A: Yes, but with limitations. After creating the environment, activate it (`conda activate myenv`) and use `pip install` to add packages. However, this can lead to dependency conflicts if the package requires non-Python libraries not managed by conda. Prefer `conda-forge` or `defaults` channels for maximum compatibility.
Q: How do I share a conda environment with a teammate?
A: Export the environment to a YAML file using `conda env export > environment.yml`, then share the file. Your teammate can recreate the environment with `conda env create -f environment.yml`. For large environments, consider using `conda-pack` to generate a portable tarball.
Q: Why does `conda create environment` sometimes fail to resolve dependencies?
A: Dependency resolution failures typically occur due to conflicting package versions, missing channels, or unsupported OS architectures. Check the error message for clues: common fixes include specifying exact versions (e.g., `python=3.9`), adding channels with `--channel conda-forge`, or updating conda itself (`conda update conda`).
Q: Is there a performance difference between `conda create environment` and `mamba create`?
A: Yes. `mamba create` uses the `libsolv` algorithm, which is significantly faster for complex environments (often 10x speedup). While functionally equivalent, `mamba` is recommended for large-scale projects or CI/CD pipelines where speed is critical.
Q: Can I delete a conda environment without affecting my base installation?
A: Absolutely. Use `conda env remove --name myenv` to delete the environment. This only removes the specified namespace and its packages; the base conda installation and other environments remain intact. Always verify the environment name to avoid accidental deletion.
Q: How do I list all existing conda environments?
A: Run `conda env list` or `conda info --envs`. This displays all environments, their paths, and the active one (marked with `*`). To see detailed package lists for a specific environment, use `conda list --name myenv`.
Q: What’s the best practice for naming conda environments?
A: Use descriptive, lowercase names with underscores (e.g., `tf_gpu_env` or `ml_project_v1`). Avoid spaces or special characters, as they can cause issues with scripts or automation tools. Also, prefix environment names with project codes if working in a team to avoid conflicts.
Q: Can I use `conda create environment` on Windows Subsystem for Linux (WSL)?
A: Yes, but with caveats. Conda environments created in WSL are Linux-native and cannot be directly used in the Windows filesystem. If you need to share environments between WSL and Windows, consider using `conda-pack` to generate a portable image or stick to Windows-native conda installations for cross-platform compatibility.
Q: How do I update all packages in a conda environment?
A: Activate the environment (`conda activate myenv`) and run `conda update --all`. This updates all packages to their latest compatible versions. For selective updates, specify packages (e.g., `conda update numpy pandas`). Always review changes with `conda list --revisions` to revert if needed.
Q: Why does my conda environment take up more disk space than expected?
A: Conda environments include pre-built binaries for all dependencies, which can bloat size. To reduce space, use `conda clean --all` to remove unused cache files. For minimal environments, prefer `conda-forge` (often smaller than `defaults`) or manually specify only essential packages.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.