How Kadane’s Algorithm Solves Maximum Subarray Problems Like a Pro
In the quiet corners of computational theory, where brute-force methods falter and inefficiency reigns, Kadane’s algorithm emerges as a beacon of efficiency. It doesn’t just solve problems—it redefines how we approach them. Whether you’re parsing financial time series for peak performance or optimizing data streams for machine learning, this algorithm cuts through the noise with a single, elegant pass. Its ability to identify the maximum sum of a contiguous subarray in linear time (O(n)) makes it indispensable, yet its origins remain surprisingly underdiscussed. The fact that it can outperform naive O(n²) approaches with minimal overhead is a testament to its brilliance, but the story behind its creation is just as compelling.
What makes Kadane’s algorithm truly remarkable isn’t just its speed—it’s the way it reframes the problem. Traditional methods treat subarrays as discrete entities, forcing nested loops and redundant calculations. Kadane’s approach, however, treats the array as a continuous stream, updating the best possible solution incrementally. This isn’t just optimization; it’s a philosophical shift in how we think about sequential data. The algorithm’s simplicity belies its power: a few variables, a single loop, and a decision-making process that feels almost intuitive once you grasp it. Yet, despite its ubiquity in coding interviews and technical assessments, many practitioners still overlook its broader implications—how it can be adapted for stock market analysis, DNA sequence scoring, or even social network influence metrics.
The algorithm’s name itself is a nod to its inventor, Joseph Kadane, whose 1984 paper laid the foundation for modern subarray optimization. But the real magic lies in its adaptability. While it’s often taught as a standalone tool, its principles extend far beyond basic array problems. It’s a building block for more complex systems, a proof of concept for greedy algorithms, and a case study in how mathematical elegance can solve real-world challenges. The question isn’t whether you need to understand it—it’s how deeply you can integrate its logic into your own problem-solving arsenal.

The Complete Overview of Kadane’s Algorithm
Kadane’s algorithm is a cornerstone of algorithmic efficiency, designed to solve the maximum subarray problem—finding the contiguous subarray within a one-dimensional array of numbers that has the largest sum. At its core, it operates on a deceptively simple premise: track the maximum sum ending at each position in the array, then compare it to the global maximum encountered so far. This dynamic programming approach ensures that no element is processed more than once, making it both time and space optimal (O(n) time, O(1) space). Its elegance lies in its ability to make locally optimal choices at each step, which collectively lead to a globally optimal solution—a hallmark of greedy algorithms.
The algorithm’s strength becomes apparent when contrasted with brute-force alternatives. A naive implementation would require checking every possible subarray (O(n²) time), which is infeasible for large datasets. Kadane’s method, however, processes the array in a single forward pass, updating two critical variables: max_current (the best sum ending at the current position) and max_global (the overall best sum found). This dual-tracking mechanism ensures that the solution is both correct and computationally efficient. Beyond its theoretical appeal, the algorithm’s practical applications span industries, from quant finance to bioinformatics, where identifying optimal sequences is paramount.
Historical Background and Evolution
The origins of Kadane’s algorithm trace back to the early 1980s, when Joseph Kadane, a statistician and computer scientist, published his seminal work in the Journal of the American Statistical Association. His paper, titled "Algorithms for Calculating the Maximum Subarray," introduced the method as a solution to a problem that had long plagued computational researchers. Prior to Kadane’s work, the problem was typically addressed using divide-and-conquer strategies, which, while theoretically sound, suffered from high constant factors and overhead. Kadane’s linear-time approach was a game-changer, offering a balance of simplicity and performance that subsequent generations of programmers would adopt wholesale.
Table of Contents
- The Complete Overview of Kadane’s Algorithm
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What is the primary use case for Kadane’s algorithm?
- Q: Can Kadane’s algorithm handle negative numbers?
- Q: How does Kadane’s algorithm compare to brute-force methods?
- Q: Are there variations of Kadane’s algorithm for specific constraints?
- Q: What industries benefit most from Kadane’s algorithm?
- Q: Can Kadane’s algorithm be parallelized for faster execution?
- Q: Is Kadane’s algorithm limited to one-dimensional arrays?
- Q: How does Kadane’s algorithm handle empty arrays or all-negative inputs?
Interestingly, the algorithm’s development wasn’t isolated to academia. Parallel advancements in computer hardware—particularly the rise of mainframe systems with limited memory—created a demand for algorithms that minimized resource usage. Kadane’s method fit perfectly into this landscape, providing a scalable solution that could handle large datasets without sacrificing speed. Over time, its influence extended beyond pure computer science. In finance, for instance, it became a tool for analyzing stock price trends, where identifying the most profitable contiguous trading window is critical. Similarly, in genomics, it’s used to score DNA sequences by maximizing similarity scores over sliding windows. The algorithm’s versatility has cemented its status as a fundamental technique, taught in universities and referenced in technical interviews worldwide.
Core Mechanisms: How It Works
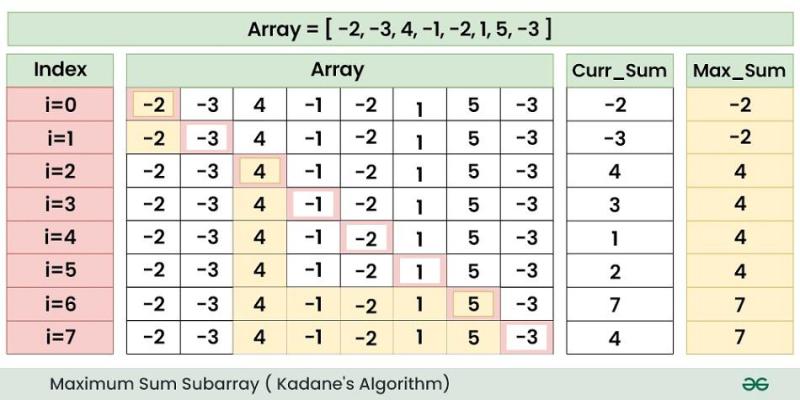
At its heart, Kadane’s algorithm is a greedy algorithm that leverages dynamic programming principles. The key insight is that the maximum subarray ending at a given position i is either the element at i itself or the sum of the maximum subarray ending at i-1 and the element at i. This recursive relationship allows the algorithm to compute the solution in linear time by maintaining two variables: max_current, which stores the maximum sum of the subarray ending at the current position, and max_global, which keeps track of the highest sum encountered during the entire traversal.
The pseudocode for the algorithm is deceptively simple:
max_current = max_global = arr[0]

for i from 1 to n-1:

    max_current = max(arr[i], max_current + arr[i])

    if max_current > max_global:

        max_global = max_current

return max_global
This loop processes each element exactly once, updating max_current to reflect whether including the current element improves the sum or if starting fresh at the current element yields a better result. The comparison with max_global ensures that the best possible sum is always retained. The algorithm’s efficiency stems from its ability to make decisions in constant time at each step, avoiding the exponential complexity of recursive or brute-force methods. This makes it particularly valuable in scenarios where real-time processing is required, such as streaming data analysis or online algorithmic trading.
Key Benefits and Crucial Impact
The allure of Kadane’s algorithm lies in its dual advantages: theoretical elegance and practical utility. It solves a problem that, at first glance, seems trivial—finding the best contiguous subarray—but does so with an efficiency that renders brute-force approaches obsolete. This isn’t just about speed; it’s about scalability. In an era where datasets grow exponentially, an O(n) solution is the difference between a feasible computation and a computational nightmare. The algorithm’s minimal space complexity (O(1)) further enhances its appeal, as it doesn’t require additional data structures or memory-intensive operations.
Beyond its technical merits, the algorithm’s impact is felt across disciplines. In finance, it’s used to identify optimal trading windows, where the "subarray" represents a sequence of profitable trades. In bioinformatics, it helps in sequence alignment by maximizing similarity scores over sliding windows. Even in social network analysis, it can be adapted to detect periods of high influence or activity. The algorithm’s adaptability is a testament to its robustness, proving that a simple idea can have far-reaching consequences when applied creatively.
"Kadane’s algorithm is a masterclass in how to solve problems by breaking them down into their simplest, most intuitive components. It’s not just about the code—it’s about the mindset."
— Joseph Kadane, Statistician and Algorithm Pioneer
Major Advantages
- Linear Time Complexity (O(n)): Processes the array in a single pass, making it ideal for large datasets.
- Constant Space Complexity (O(1)): Uses only a few variables, regardless of input size.
- Adaptability: Can be extended to solve variations of the maximum subarray problem, such as finding the longest subarray with a positive sum.
- Intuitive Logic: The greedy approach aligns with human problem-solving instincts, making it easier to debug and modify.
- Widespread Applicability: Used in finance, genomics, signal processing, and more, demonstrating its cross-disciplinary relevance.
Comparative Analysis
While Kadane’s algorithm is the gold standard for the maximum subarray problem, other approaches exist, each with trade-offs in terms of time, space, and practicality. Understanding these alternatives provides context for why Kadane’s method is preferred in most scenarios.
| Approach | Key Characteristics |
|---|---|
| Brute Force | Checks all possible subarrays (O(n²) time). Simple but impractical for large n. |
| Divide and Conquer | Recursively splits the array (O(n log n) time). More efficient than brute force but complex to implement. |
| Dynamic Programming (Kadane’s) | Linear time (O(n)) with constant space. Optimal for most real-world applications. |
| Sliding Window (Modified Kadane) | Used when subarrays must meet additional constraints (e.g., fixed length). Still O(n) but with adjusted logic. |
The table above highlights why Kadane’s algorithm stands out. While brute-force methods are easy to understand, their inefficiency makes them unsuitable for large-scale problems. Divide-and-conquer approaches offer better performance but introduce overhead from recursion and merging steps. Kadane’s method strikes the perfect balance, combining simplicity with efficiency. Modified versions, such as sliding window adaptations, further extend its utility when constraints like fixed subarray lengths are introduced.
Future Trends and Innovations
The principles underlying Kadane’s algorithm are likely to remain relevant as computational challenges evolve. One emerging trend is its integration into real-time systems, where streaming data requires instantaneous processing. Adaptations of the algorithm are already being explored in online machine learning, where maintaining a running maximum over data streams is critical. Additionally, as quantum computing matures, researchers are investigating how classical algorithms like Kadane’s can be optimized for quantum parallelism, potentially reducing time complexity further.
Another frontier is the algorithm’s application in explainable AI. By providing interpretable results—such as identifying the most influential subarrays in a dataset—Kadane’s method can serve as a bridge between complex models and human understanding. In fields like genomics, where sequences must be analyzed for functional motifs, hybrid approaches combining Kadane’s logic with deep learning are being tested. The future may also see the algorithm extended to multi-dimensional arrays or graph structures, broadening its scope beyond one-dimensional problems. As data grows more complex, the core ideas of Kadane’s algorithm—greedy optimization and dynamic decision-making—will continue to inspire innovative solutions.

Conclusion
Kadane’s algorithm is more than just a tool for solving the maximum subarray problem; it’s a paradigm of efficient computation. Its ability to process data in linear time with minimal resources makes it indispensable in fields where performance matters. The algorithm’s simplicity belies its depth, offering a blueprint for how to approach problems by focusing on incremental improvements and global optimization. Whether you’re a programmer optimizing code, a data scientist analyzing trends, or a researcher exploring new computational frontiers, understanding Kadane’s method equips you with a powerful lens to view sequential data.
The real takeaway isn’t just about memorizing the algorithm—it’s about recognizing the patterns it embodies. The same logic that solves the maximum subarray problem can be adapted to tackle a wide range of challenges, from financial modeling to biological sequence analysis. As technology advances, the principles of Kadane’s algorithm will continue to evolve, but its core—making locally optimal choices to achieve global efficiency—will remain a timeless cornerstone of algorithmic design.
Comprehensive FAQs
Q: What is the primary use case for Kadane’s algorithm?
A: The primary use case is solving the maximum subarray problem, where the goal is to find the contiguous subarray within a one-dimensional array that has the largest sum. It’s widely used in finance (e.g., identifying profitable trading windows), bioinformatics (e.g., sequence scoring), and data analysis (e.g., detecting peaks in time-series data).
Q: Can Kadane’s algorithm handle negative numbers?
A: Yes, Kadane’s algorithm works seamlessly with negative numbers. It dynamically decides whether to include the current element in the existing subarray or start a new subarray at that element, ensuring the maximum sum is always considered, even if it involves negative values.
Q: How does Kadane’s algorithm compare to brute-force methods?
A: Brute-force methods check all possible subarrays, resulting in O(n²) time complexity, which is inefficient for large datasets. Kadane’s algorithm processes the array in O(n) time with O(1) space, making it exponentially faster and more scalable. For an array of size 10,000, brute force would require ~50 million operations, while Kadane’s would perform just 10,000.
Q: Are there variations of Kadane’s algorithm for specific constraints?
A: Yes. For example, a sliding window variation can enforce a fixed subarray length, while another might maximize the product of subarray elements instead of the sum. These adaptations retain the core O(n) efficiency but adjust the logic to meet specific problem requirements.
Q: What industries benefit most from Kadane’s algorithm?
A: Industries leveraging Kadane’s algorithm include:
- Finance: Stock price analysis, portfolio optimization.
- Bioinformatics: DNA/protein sequence scoring.
- Machine Learning: Feature selection, anomaly detection.
- Signal Processing: Peak detection in time-series data.
- Social Networks: Identifying periods of high engagement.
Q: Can Kadane’s algorithm be parallelized for faster execution?
A: Parallelizing Kadane’s algorithm is non-trivial due to its sequential nature, but research has explored dividing the array into chunks and merging results. However, the overhead often outweighs the benefits for small to medium-sized datasets. For truly massive data, hybrid approaches (e.g., combining with MapReduce) are being investigated.
Q: Is Kadane’s algorithm limited to one-dimensional arrays?
A: The classic algorithm is designed for one-dimensional arrays, but its principles can be extended to higher dimensions or graphs with modifications. For example, in two-dimensional matrices, dynamic programming variants (like Kadane’s but with nested loops) can find the maximum submatrix sum, though these lose the O(n) efficiency.
Q: How does Kadane’s algorithm handle empty arrays or all-negative inputs?
A: If the array is empty, the algorithm typically returns 0 or an error, depending on implementation. For all-negative inputs, it correctly identifies the least negative subarray (or the single largest element if no positive subarray exists). This is handled naturally by the max_current and max_global comparisons.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Bevvy.